Failure Mode and Effects Analysis: A Strategic Approach to Operational Resilience and Risk Mitigation

In the complex landscape of modern global enterprise, where interconnected digital and physical systems underpin every transaction, the capacity to anticipate systemic failure is a critical competency. Failure Mode and Effects Analysis (FMEA) serves as a cornerstone of this discipline, offering a structured, data-driven methodology for identifying potential vulnerabilities in products, services, and operational workflows. By shifting the organizational mindset from reactive firefighting to proactive, worst-case-scenario planning, leadership teams can systematically evaluate risks before they manifest as catastrophic disruptions.
The necessity of such rigor was starkly illustrated by the 2017 British Airways IT failure, a landmark case study in operational vulnerability. The incident, which paralyzed the airline’s global operations over a busy bank holiday weekend, provides a sobering look at how a localized power surge can trigger a cascading collapse across an entire organization. While early reports speculated on the total financial damage, International Airlines Group (IAG) later confirmed an estimated gross cost of approximately £80 million. This figure encompasses not only immediate technical remediation but also the massive logistical burden of processing tens of thousands of displaced passengers, rebooking flights, and managing the resulting reputational fallout.
Defining the FMEA Framework
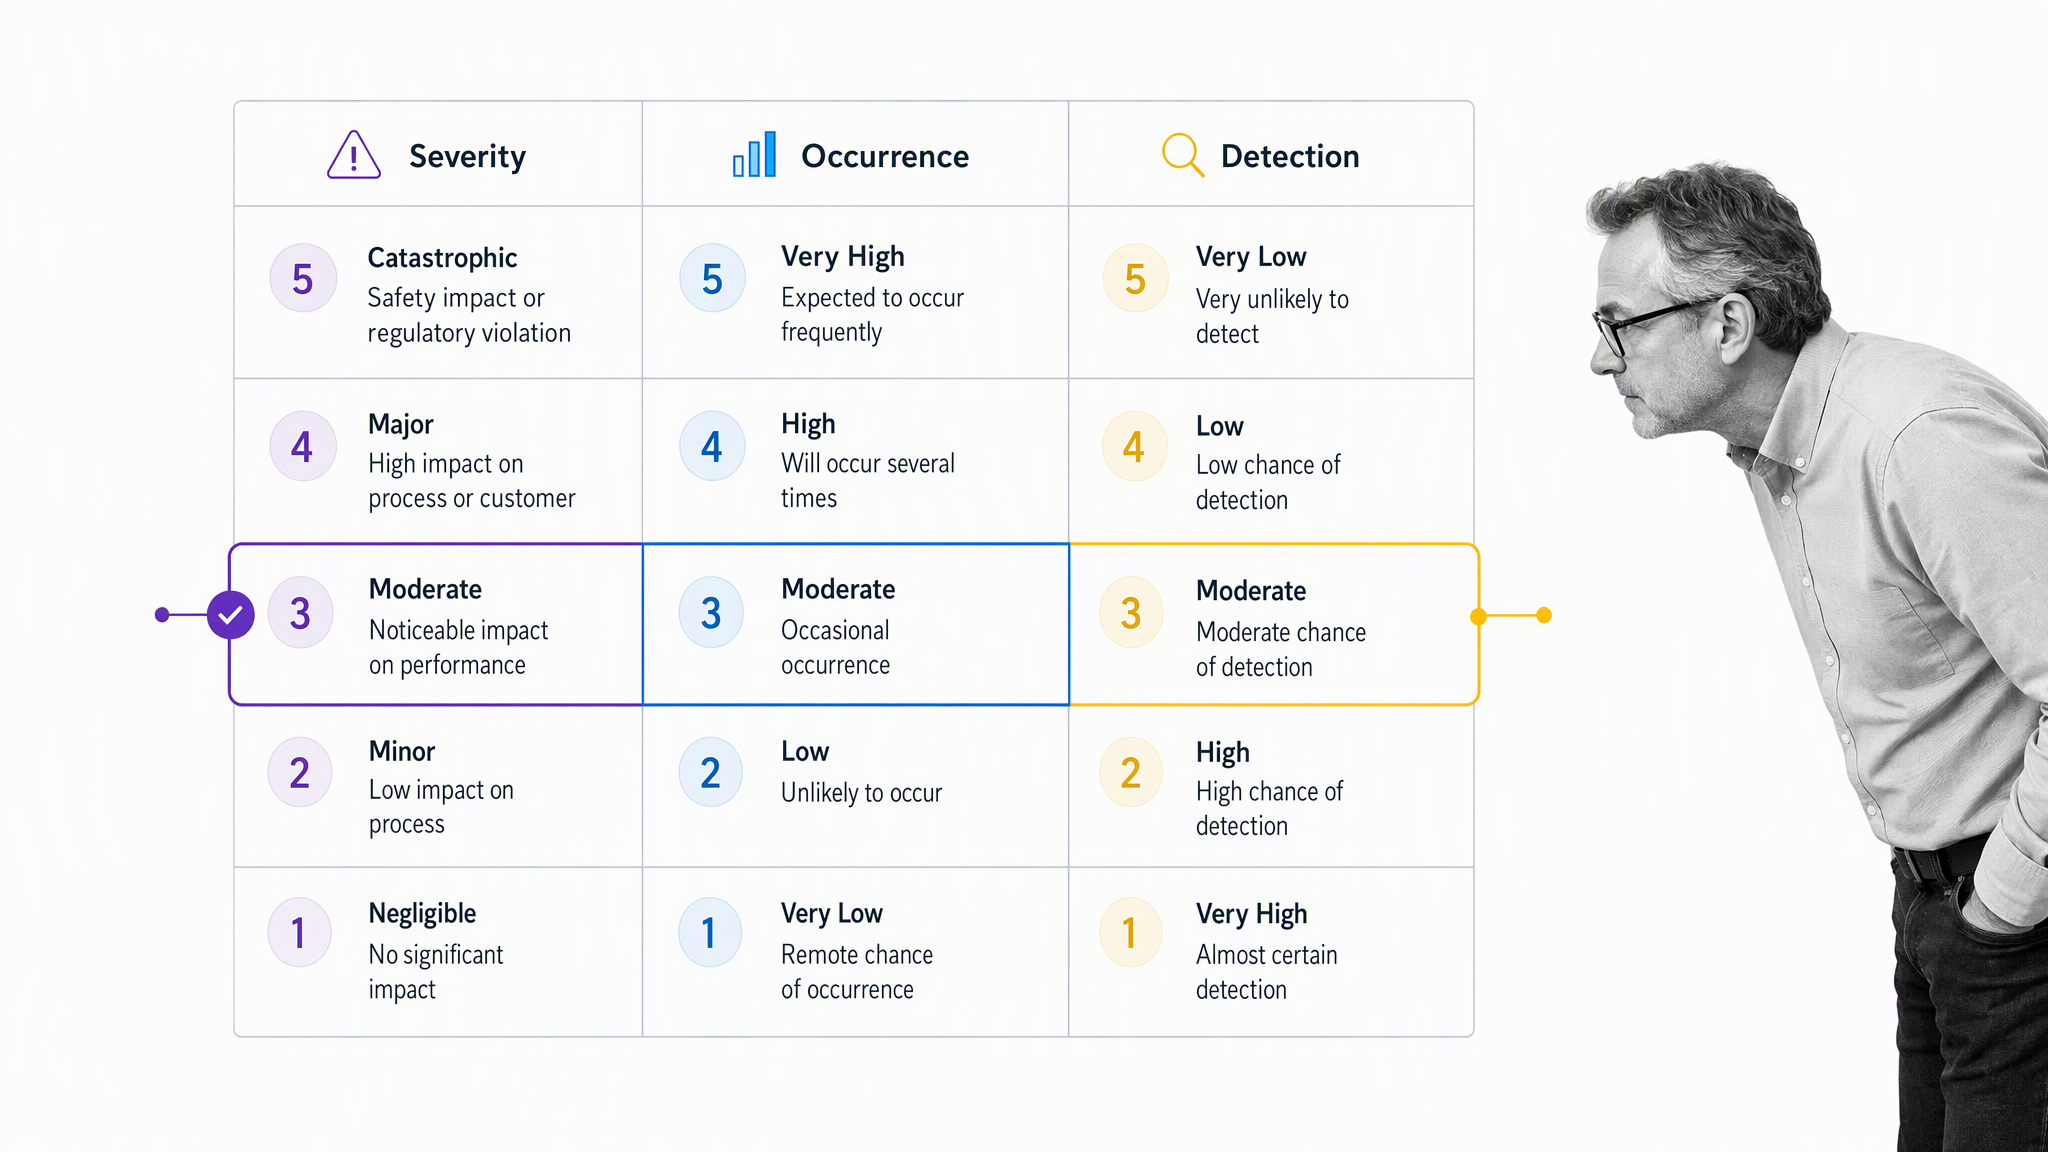
At its core, FMEA is a rigorous, iterative process used to identify how a system might fail and what the consequences of that failure would be. It is not merely a box-ticking exercise; it is a collaborative audit of reality. The methodology operates on three primary metrics: Severity (the impact of the failure on the end-user), Occurrence (the likelihood of the failure happening), and Detection (the ability of existing controls to catch the issue before it reaches the customer).
By assigning a numerical value to each of these categories, teams calculate a Risk Priority Number (RPN). This allows stakeholders to move beyond subjective anxiety and prioritize the most critical threats to the operation. While the RPN is a useful tool, it is secondary to the qualitative insights gained during the mapping process. Effective FMEA demands that stakeholders from across the organization—engineering, operations, customer service, and IT—contribute to the analysis. A siloed assessment is often blind to the dependencies that cause small, isolated errors to mushroom into enterprise-level crises.
The Anatomy of the 2017 British Airways Crisis
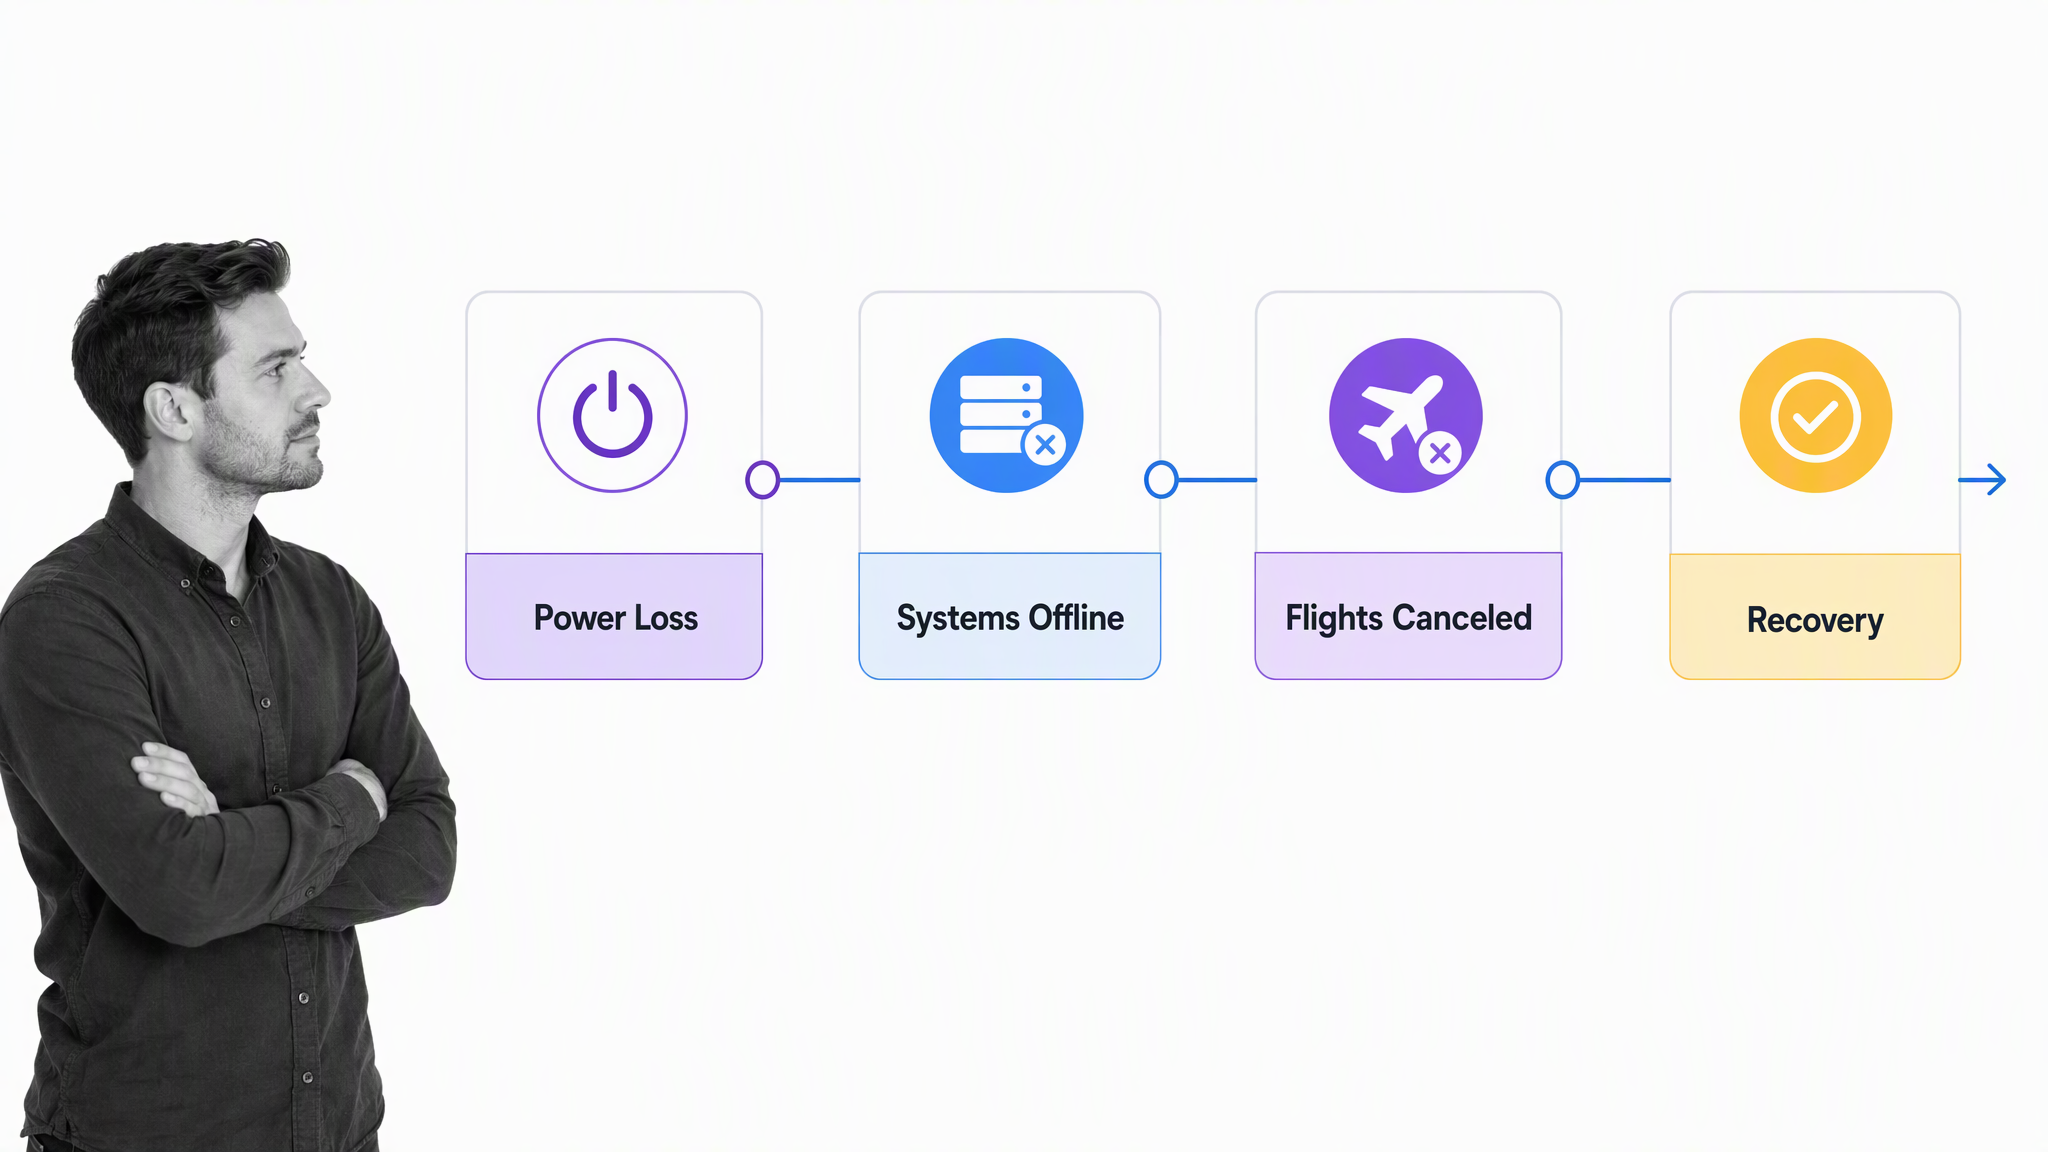
To understand the practical application of FMEA, one must examine the specific mechanics of the May 2017 British Airways outage. On the morning of May 27, a significant power failure occurred at a primary data center near Heathrow Airport. The subsequent sequence of events revealed a failure in the robustness of the backup power infrastructure.
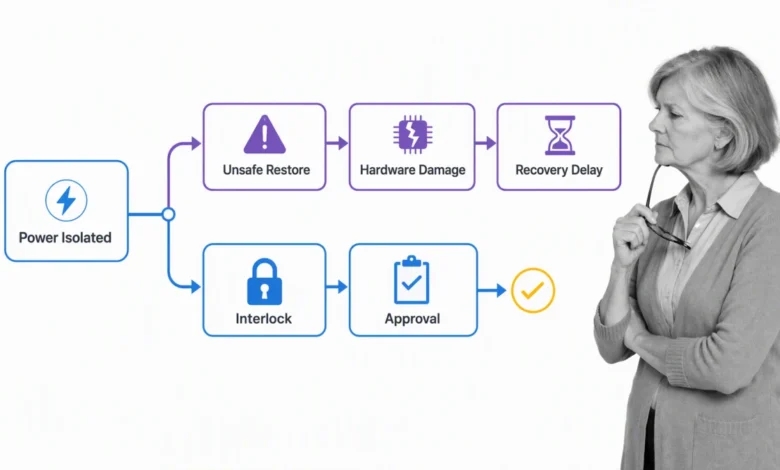
According to technical reports and subsequent internal reviews, the issue was not merely the loss of mains power, but the uncontrolled, erratic restoration of that power. This surge resulted in physical damage to critical IT hardware, effectively locking the airline out of its own booking, baggage, and check-in systems. The timeline of the disruption was brutal:
- May 27: The initial power event leads to a total collapse of IT systems, forcing the immediate cancellation of hundreds of flights.
- May 28-29: The chaos intensifies over the Bank Holiday weekend, with thousands of passengers stranded at airports globally.
- June: IAG begins the process of quantifying the £80 million in damages, which included compensation payouts, hotel accommodations, and the long-term cost of lost passenger goodwill.
From a process-engineering perspective, the crisis highlighted a breakdown in redundancy. The Uninterruptible Power Supply (UPS) system—designed specifically to prevent such an outcome—failed to act as the reliable bridge it was intended to be. The incident underscores a vital lesson for risk managers: redundancy is not a set-it-and-forget-it feature. If the failover mechanism itself is not subject to rigorous, periodic FMEA, it can become a single point of failure.
Operational Implications and Root Cause Analysis
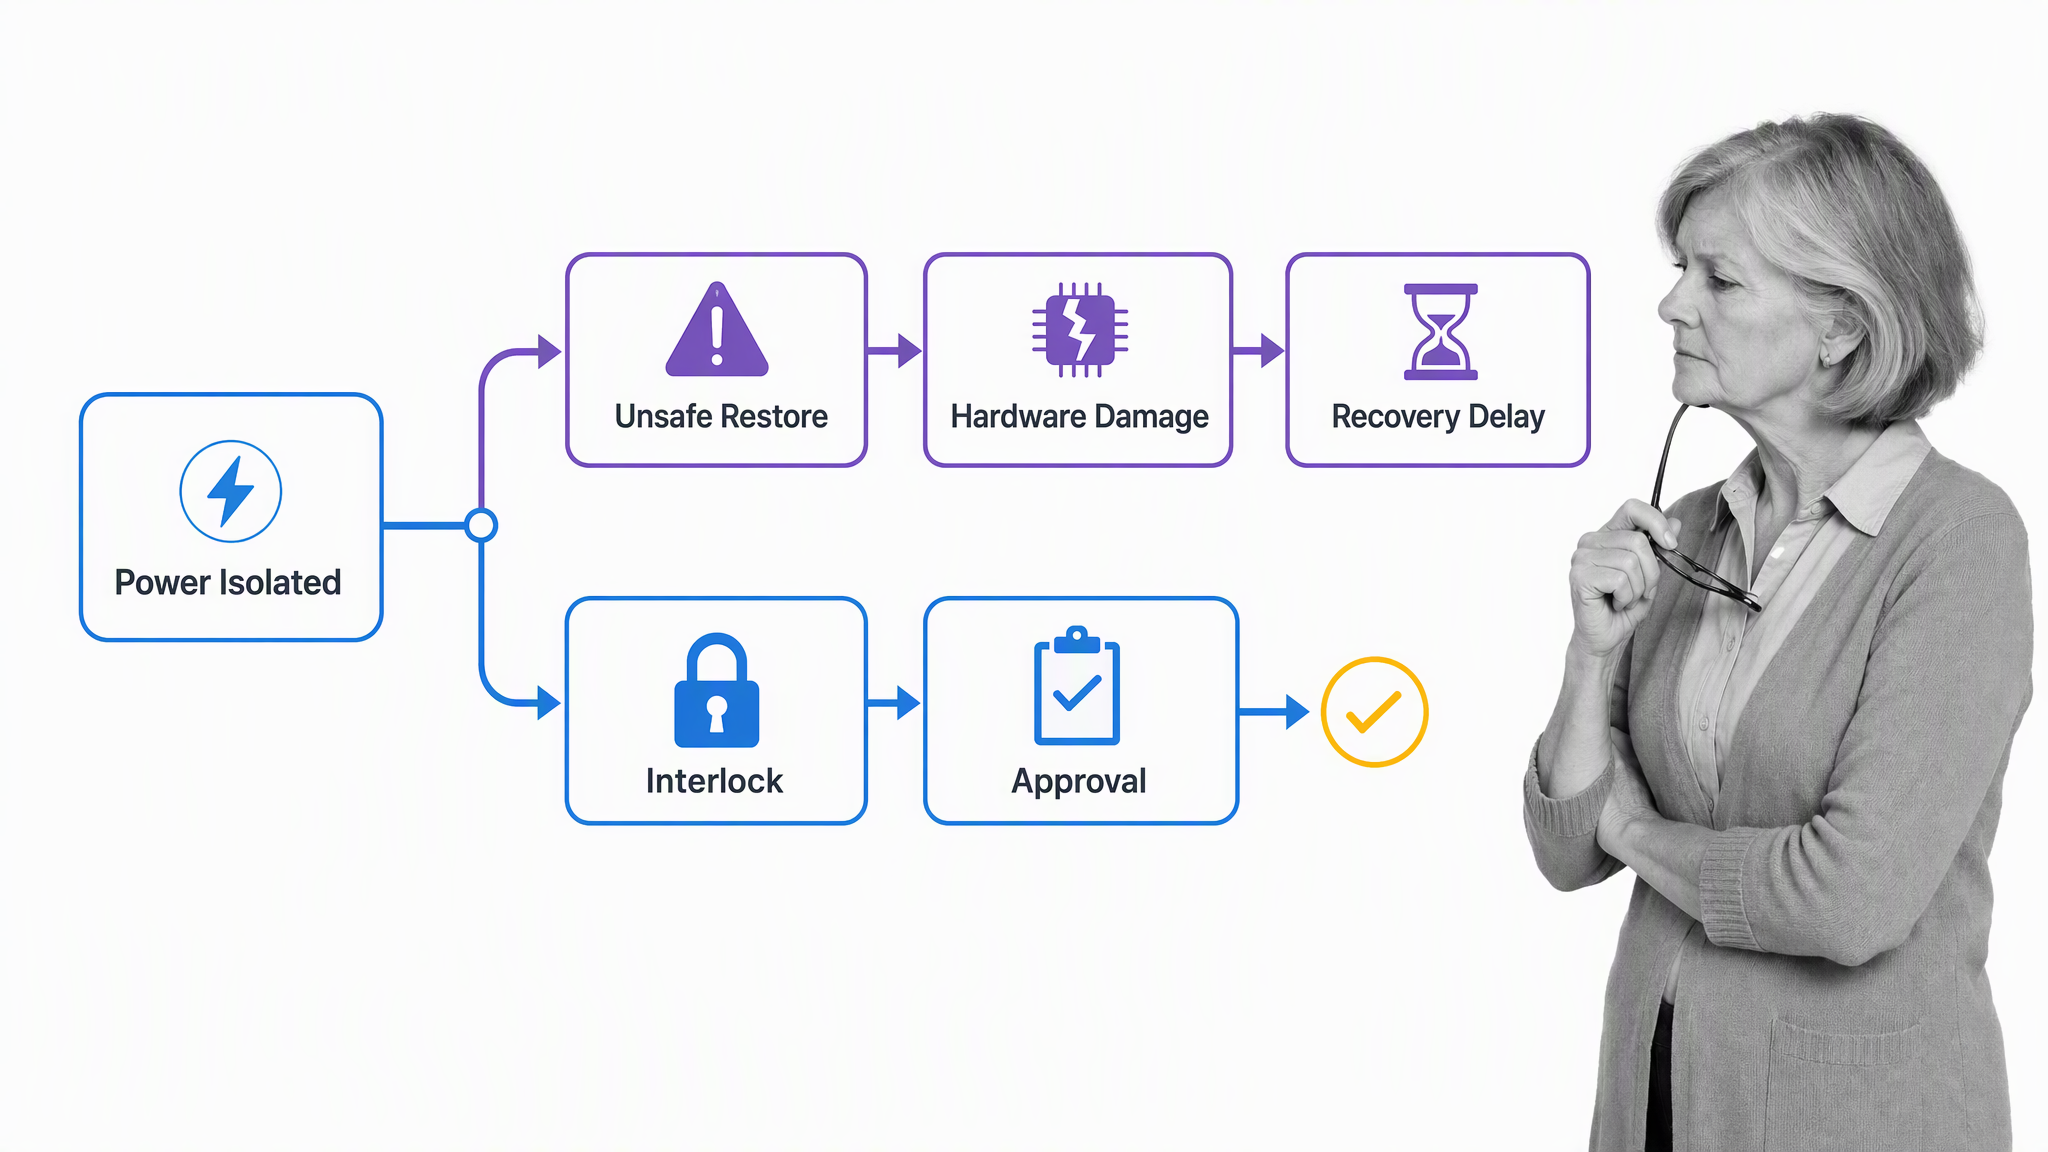
When evaluating why the British Airways incident occurred, analysts often point toward the "normalization of deviance"—a phenomenon where organizations become desensitized to small, recurring technical quirks until they culminate in a major disaster. In the context of the 2017 event, the crucial questions centered on governance: Who had the authority to initiate power restoration? Were there written, verified protocols for manual overrides? Were there technical interlocks that could have prevented the restart while systems were in a vulnerable state?
An FMEA approach would have treated "uncontrolled power restoration" as a high-severity failure mode. By mapping the chain of causality, a team could have implemented "hard" controls—such as physical interlocks or automated, staged energization protocols—rather than relying on the judgment of individuals working under extreme pressure.
In modern, automated environments, the goal is to remove the burden of perfect performance from human operators. By designing a system that is "fail-safe" or "fail-soft," companies ensure that if a component breaks, the system defaults to a safe state rather than a catastrophic one.
Implementing FMEA in Modern Business Workflows
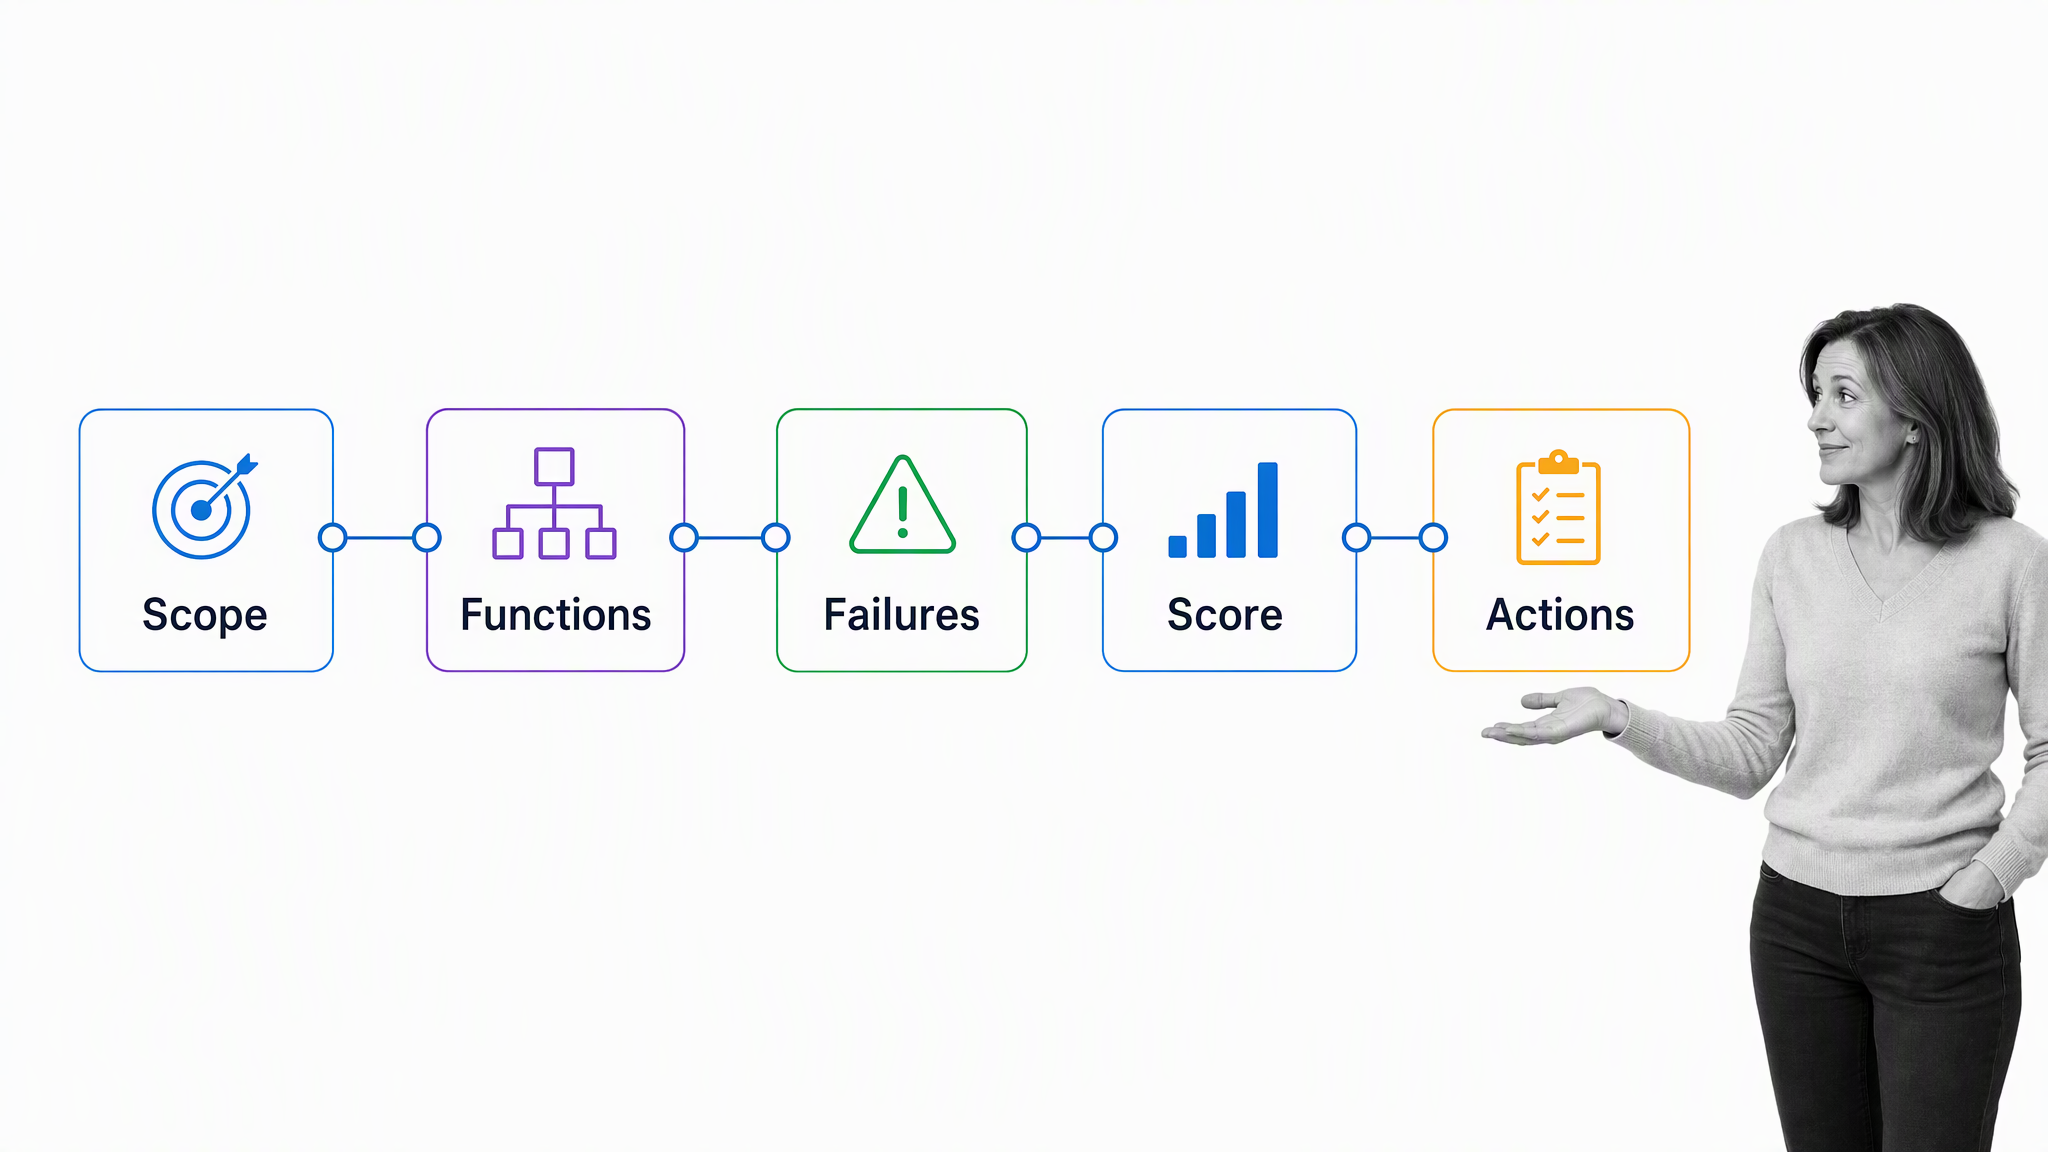
For organizations looking to integrate FMEA into their quality management systems, the implementation must be disciplined. The following five-step workflow provides a standard for execution:
- Scoping: Clearly define the boundary of the process being analyzed. What are the inputs, the steps, and the expected outputs?
- Identification: Brainstorm all possible ways each step could fail. This requires an honest, sometimes uncomfortable, look at human error, technical limitations, and external environmental factors.
- Effect Analysis: For each failure mode, determine the downstream consequences. How does this impact the customer, the bottom line, and the staff?
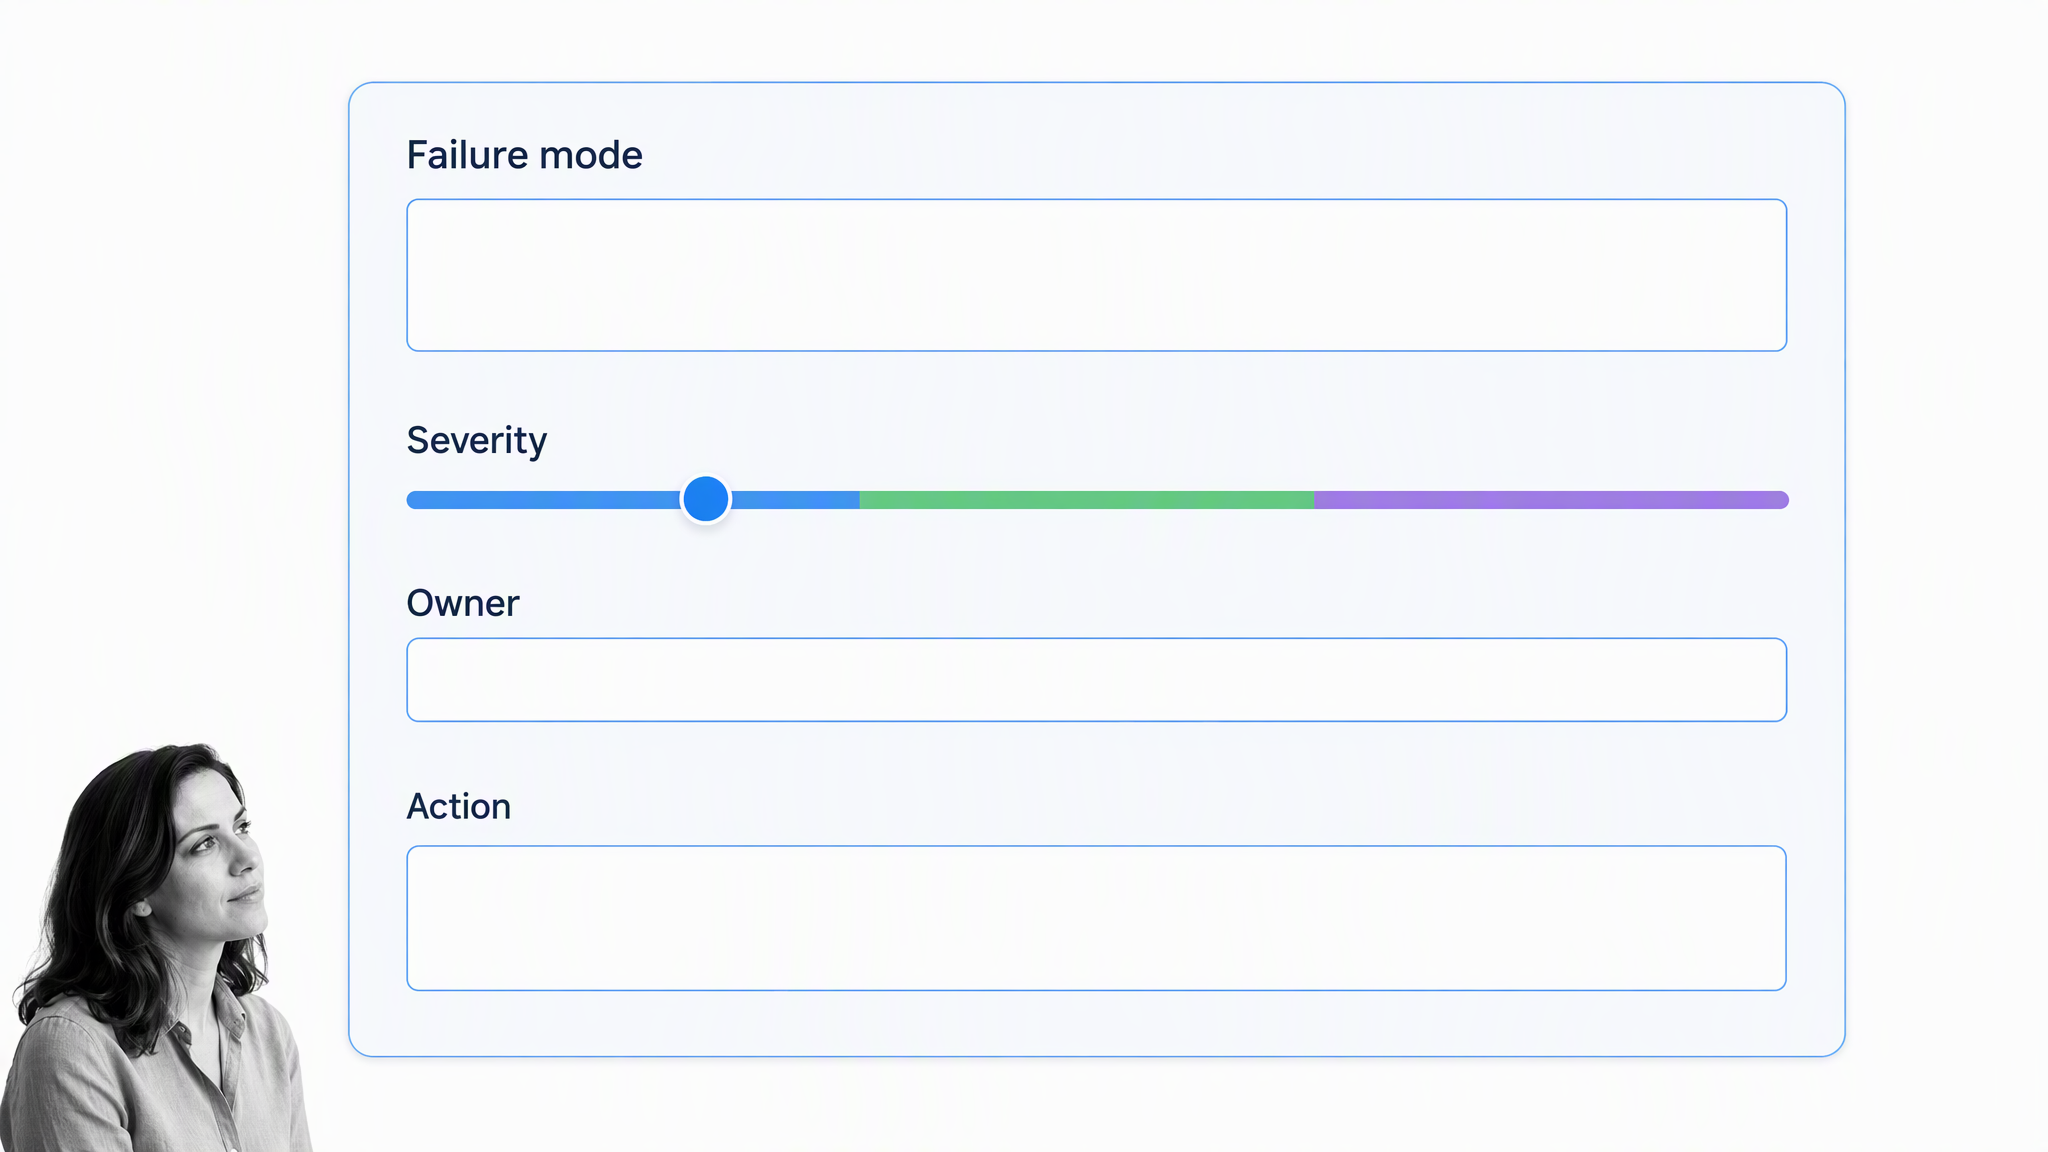
- Scoring and Prioritization: Apply the S-O-D (Severity, Occurrence, Detection) criteria to rank risks.
- Control and Mitigation: Develop specific actions to reduce risk. This might involve changing the process design, adding monitoring sensors, or implementing new training requirements.
Crucially, this analysis must be documented. In highly regulated industries—such as aviation, healthcare, or financial services—this documentation serves as the essential evidence required for audits and compliance. It acts as an institutional memory, preventing the organization from repeating the same mistakes when personnel change or technologies are upgraded.
Broader Impacts and Lessons for the Industry
The British Airways case serves as a reminder that in an interconnected, globalized economy, technical debt is a financial liability. The £80 million cost was not just an IT expense; it was an operational tax paid for the lack of a resilient, tested, and audited failover architecture.
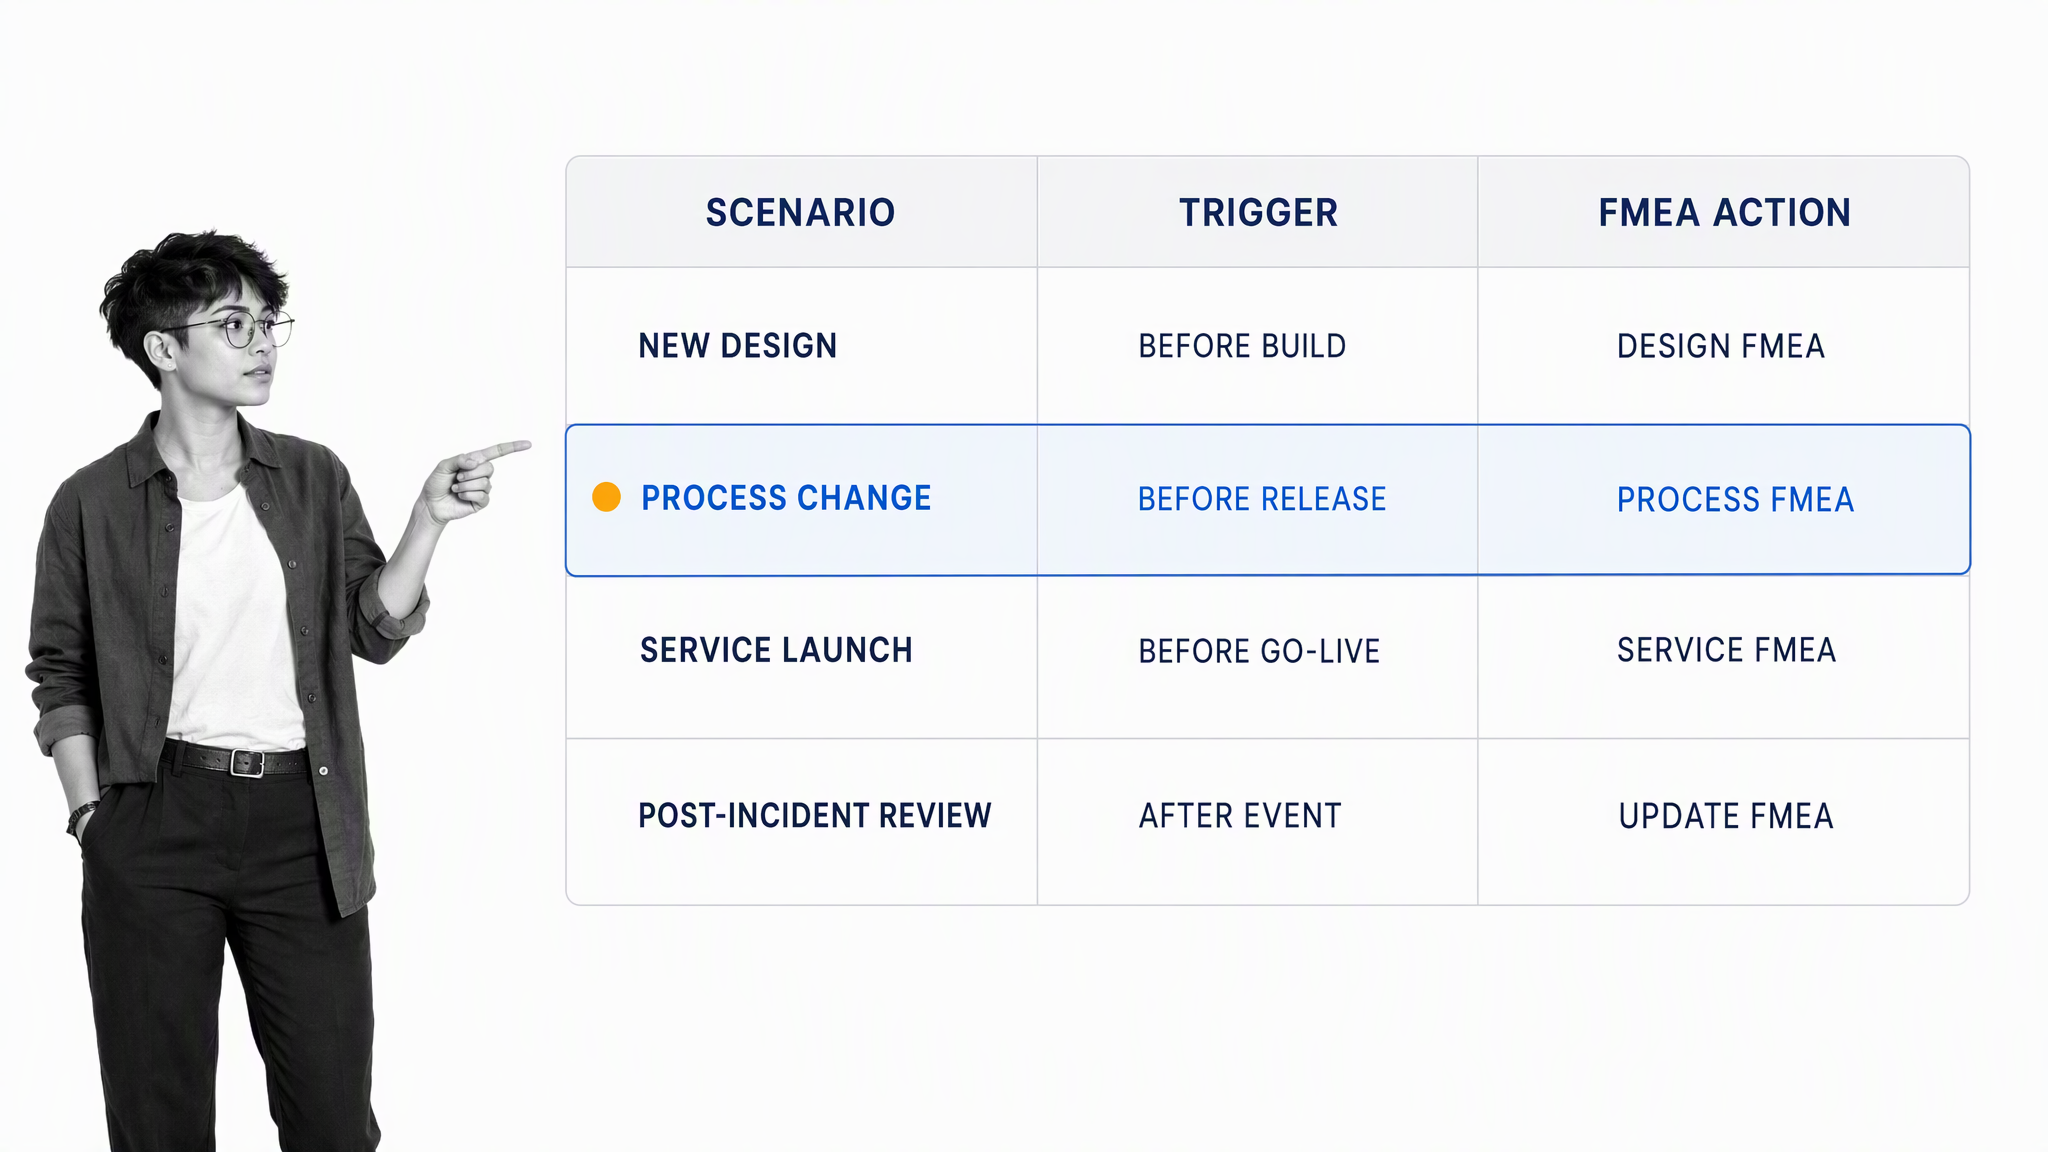
The lesson extends far beyond the airline industry. Every business—from a small e-commerce startup to a multinational manufacturing firm—relies on a stack of processes that are susceptible to failure. When an organization undergoes a period of significant change, such as migrating to the cloud, updating legacy infrastructure, or scaling into a new market, it is at its most vulnerable. These are the moments when FMEA is not just a useful tool, but a survival imperative.
By viewing every process as a potential failure point, management can transform a culture of passive optimism into one of active, disciplined prevention. This does not mean the organization becomes stagnant or overly cautious. Rather, it means that the organization gains the confidence to innovate, knowing that it has already mapped the "known unknowns" and established the controls necessary to navigate them.
In conclusion, FMEA remains one of the most effective tools in the quality management arsenal. It allows teams to look into the future, visualize the potential for disruption, and build the defenses necessary to ensure that when the inevitable challenges arise, the organization remains intact. Whether it is a data center power supply or a simple accounting process, the principles of disciplined failure analysis remain the same: identify the mode, assess the effect, and prioritize the defense.