Seven Common Token-Waste Patterns in Production AI Agent Systems and the Architectural Fixes That Address Each One.

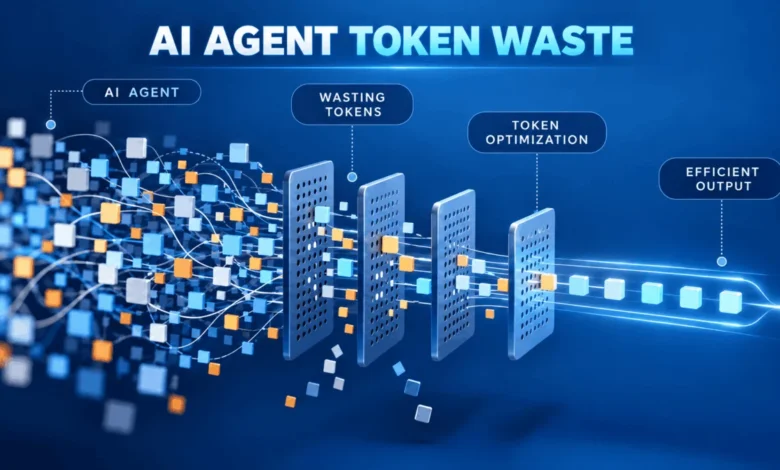
The rapid proliferation of Large Language Model (LLM) agent frameworks has shifted the engineering challenge from model prototyping to production sustainability. While a weekend-built agent can demonstrate impressive capabilities in a sandboxed environment, scaling these systems to enterprise-grade production introduces significant economic and technical hurdles. Central to these challenges is the "token-waste" phenomenon, where architectural inefficiencies result in runaway API costs, increased latency, and a degradation of reasoning accuracy. As organizations move toward long-lived agents that perform multi-step tasks, the naive implementation—treating the context window as an infinite append-only log—has become the primary driver of unsustainable cloud expenditure.
The Economics of Contextual Overhead
In the current ecosystem of AI development, companies pay for inference based on the volume of tokens processed. Input tokens, which include the prompt and all associated history, represent the bulk of the cost for complex agentic workflows. When developers treat the context window as a "system of record" rather than an ephemeral buffer, they inadvertently force the model to re-process thousands of tokens of historical data with every request.
This leads to a quadratic increase in latency, as the attention mechanism of transformer models scales with the square of the sequence length. Industry data suggests that for agents operating at 20 turns or more, unoptimized context management can increase monthly inference bills by as much as 400% compared to a system utilizing sliding window summarization or state offloading.
The Append-Only Trap: Context Window Accumulation
The most prevalent architectural failure is the "Append-Only" design pattern. In this configuration, every user interaction, tool output, and reasoning trace is appended to a central message array. By the time an agent reaches its twentieth turn, the LLM is effectively re-reading its entire operational history.
The industry-standard solution involves the implementation of a sliding context window coupled with semantic rolling summarization. By retaining only the most recent "N" turns verbatim and compressing older interactions into a dense background summary, engineers can maintain context continuity without the compounding cost of redundant token processing. Furthermore, structural state—such as persistent user preferences or session IDs—should be offloaded to dedicated databases like Redis or PostgreSQL. This separates durable state from the ephemeral context required for immediate inference.
Inefficient Tool Result Ingestion
Third-party API integrations, such as those with Stripe, AWS, or Jira, often return verbose, deeply nested JSON payloads designed for machine-to-machine communication. Injecting these raw responses directly into an agent’s context window is a significant source of waste. A single, poorly filtered API response can consume thousands of tokens, the vast majority of which provide zero utility for the model’s reasoning.
Engineering teams are increasingly adopting a middleware transformation layer. By stripping non-essential fields, removing null values, and converting JSON to more token-efficient formats like YAML or structured Markdown, developers can reduce tool-result consumption by up to 70%. However, this requires careful design to ensure that critical metadata, such as pagination cursors or unique identifiers, is not inadvertently pruned during the transformation.
Retrieval Thrash and the "Grep-and-Dump" Problem
In the realm of Retrieval-Augmented Generation (RAG) and coding assistants, developers often rely on naive text matching. When an agent requires information from a codebase, the orchestrator frequently retrieves and dumps entire files into the prompt. This "encyclopedic" approach to data retrieval forces the model to ignore irrelevant lines of code to find a single function.
Advanced systems are now shifting toward AST-aware (Abstract Syntax Tree) retrieval. By parsing code into a call graph during the indexing phase, systems can provide the agent with only the function signature, its docstring, and immediate dependencies. This approach reduces token usage by orders of magnitude and minimizes the probability of the model hallucinating based on stale or irrelevant code snippets.
The Cost of Static Tool Schema Bloat
Large-scale agentic systems often define a registry of 30 to 50 tools, injecting the full schema of each tool into every prompt. This creates a "schema bloat" that consumes significant token real estate even when most tools are irrelevant to the current task.
Architects are responding by implementing context-aware tool pruning governed by finite state machines. In this architecture, the agent’s current operational state—such as "Discovery" vs. "Execution"—dictates which tool schemas are injected. While this creates a tension with prompt caching—since changing the injected tool set invalidates the cache—the net reduction in input tokens for high-volume agents typically outweighs the cache-miss penalties.
Mitigating Unbounded Reasoning Loops
Autonomous agents are prone to entering "reasoning loops" where a failed tool call triggers an automated retry, which fails again, leading to a cascade of wasted output tokens. Because output tokens are typically billed at a higher rate than input tokens, an unconstrained agent can rapidly exhaust a budget.
The implementation of a "circuit breaker" at the orchestrator level is now considered a mandatory production guardrail. By enforcing maximum retry counts and capping the output budget per action, developers prevent runaway billing. In instances where a task exceeds these limits, the system should be designed to escalate to a human operator, ensuring that the cost of failure is contained.
Maximizing Cache Hits Through Prompt Prefixing
Modern LLM providers offer prompt caching, which allows developers to avoid recomputing attention for static prompt prefixes. However, many developers inadvertently defeat these optimizations by injecting dynamic variables—such as current timestamps or user-specific context—at the very top of their prompts.
To maximize efficiency, engineers should adopt a strict "static-to-dynamic" gradient. By placing persistent system prompts and organizational style guides at the top of the request, and moving dynamic variables to the bottom, systems can significantly increase the frequency of cache hits. While this requires careful management of TTL (Time-To-Live) configurations, it remains one of the most effective ways to lower latency and costs in high-throughput environments.
Cascaded Routing and the Future of Inference Efficiency
Finally, the practice of using frontier-tier models for simple, repetitive tasks represents an avoidable operational expense. Routing simple classification or extraction tasks to smaller, high-speed models—such as Gemini Flash or Haiku-class models—while reserving frontier models for complex multi-step reasoning allows for a tiered pricing strategy.
Using open-source routing libraries like LiteLLM, organizations can implement logic that shifts traffic based on task complexity. This "cascaded" approach ensures that resources are allocated according to the actual difficulty of the input.
Broader Implications and Long-Term Stability
The transition from prototype to production agent requires a fundamental shift in perspective. Token optimization is no longer a peripheral cost-saving exercise; it is a critical component of system stability. As agents continue to evolve, the accumulation of stale data and inefficient reasoning cycles will increasingly be viewed as a data quality issue rather than a simple financial one.
Engineers must prioritize deterministic, observable, and efficient architectures from the earliest stages of development. By implementing these seven patterns—sliding windows, transformed tool inputs, AST-aware retrieval, dynamic schema pruning, circuit breakers, cache-conscious prefixing, and cascaded routing—developers can ensure their agents remain both financially viable and technically robust as they scale to meet the demands of enterprise production environments. The compounding effect of these design choices will ultimately define the longevity and success of the next generation of autonomous AI systems.