Bridging the Gap from Demo to Production: Understanding the AI Agent Harness and Architectural Frameworks

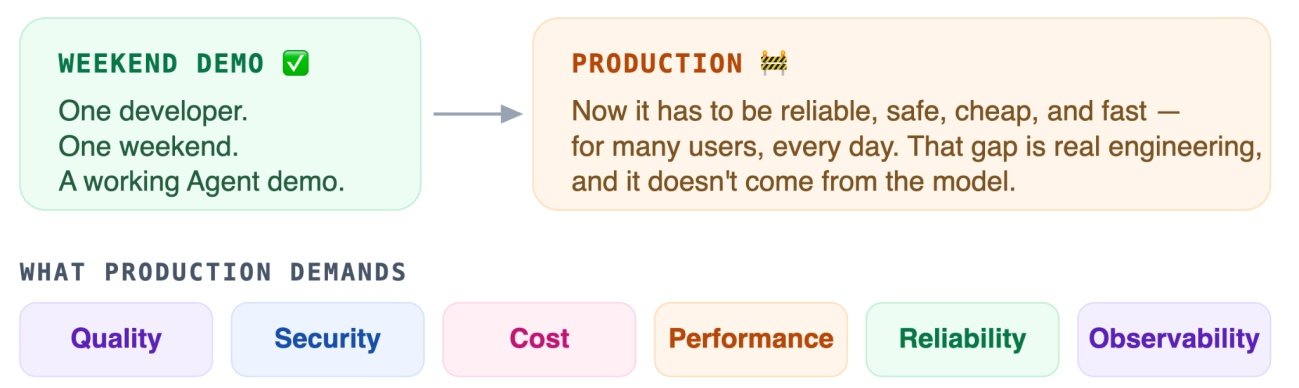
The rapid evolution of generative artificial intelligence has fundamentally shifted software development cycles, reducing the time required to spin up a basic conversational demo from weeks to a single afternoon. However, enterprise architects and engineering leaders increasingly recognize a profound divergence between a functional prototype and a production-grade artificial intelligence agent. While a proof-of-concept can rely heavily on raw foundation model outputs, moving that agent into a live production environment requires a robust, secure, and observable infrastructure layer. This foundational infrastructure—encompassing memory management, tool routing, security guardrails, cost controls, and telemetry tracking—is known in modern systems architecture as the agent harness.
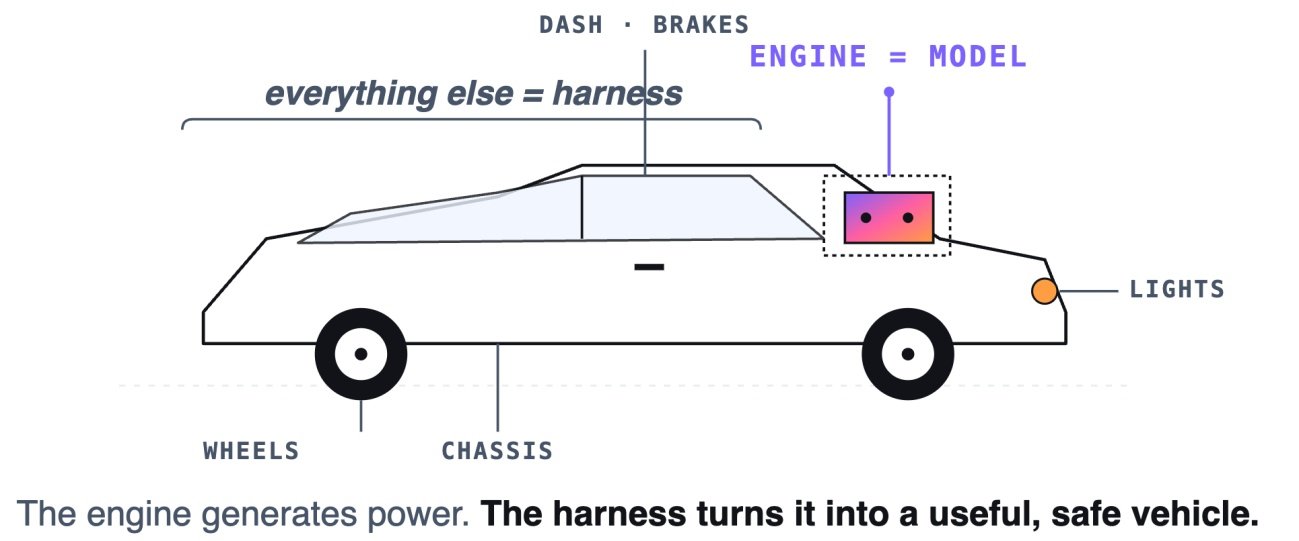
The concept of the agent harness has crystallized into a critical architectural category. Industry analysts and platform engineers note that while foundation models supply the core computational reasoning and cognitive engine, they cannot operate securely or reliably in isolation. Without a surrounding structural framework, an agent lacks persistence across user sessions, secure API integrations, cost monitoring, and automated debugging capabilities. The agent harness acts analogously to an automotive chassis, brakes, dashboard, and seatbelts: the engine provides the raw power, but the harness ensures the overall vehicle is safe, controllable, and reliable enough for public deployment.
The Dual Architecture of an Agent Harness
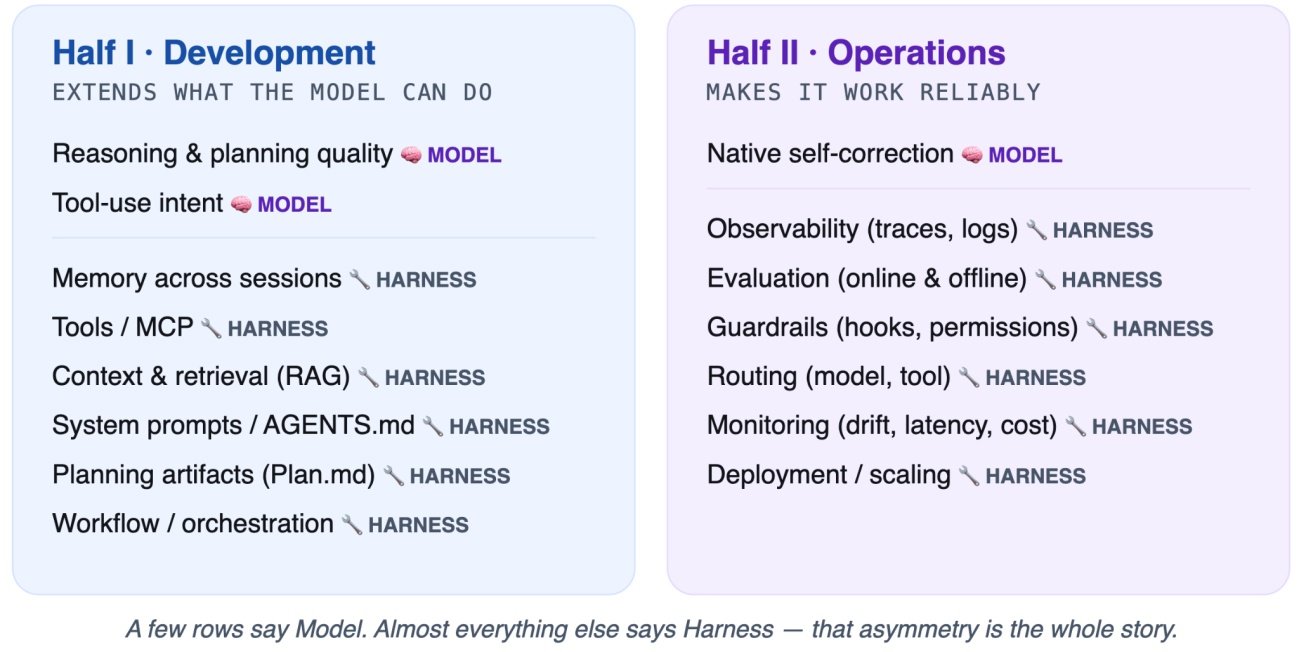
To understand how modern enterprises engineer reliable artificial intelligence systems, architects typically divide the agent harness into two primary functional categories: development and operations.
The development domain focuses on extending the operational reach of the foundation model. This includes multi-session memory management, dynamic tool orchestration through standards like the Model Context Protocol (MCP), context retrieval-augmented generation (RAG), and prompt engineering. These components determine what the agent can access, remember, and execute when processing user requests.
Conversely, the operational domain governs system reliability, safety, and governance once live users interact with the application. Rooted heavily in traditional DevOps principles adapted for non-deterministic workloads, the operational half encompasses observability, automated evaluation frameworks, behavioral guardrails, intelligent model routing, drift monitoring, and token cost attribution. Industry specialists emphasize that while a stronger foundation model elevates overall performance, treating an artificial intelligence agent as a complete product requires mastering these operational constraints.
Two Paradigms: Harness-as-a-Service versus Self-Managed Stacks
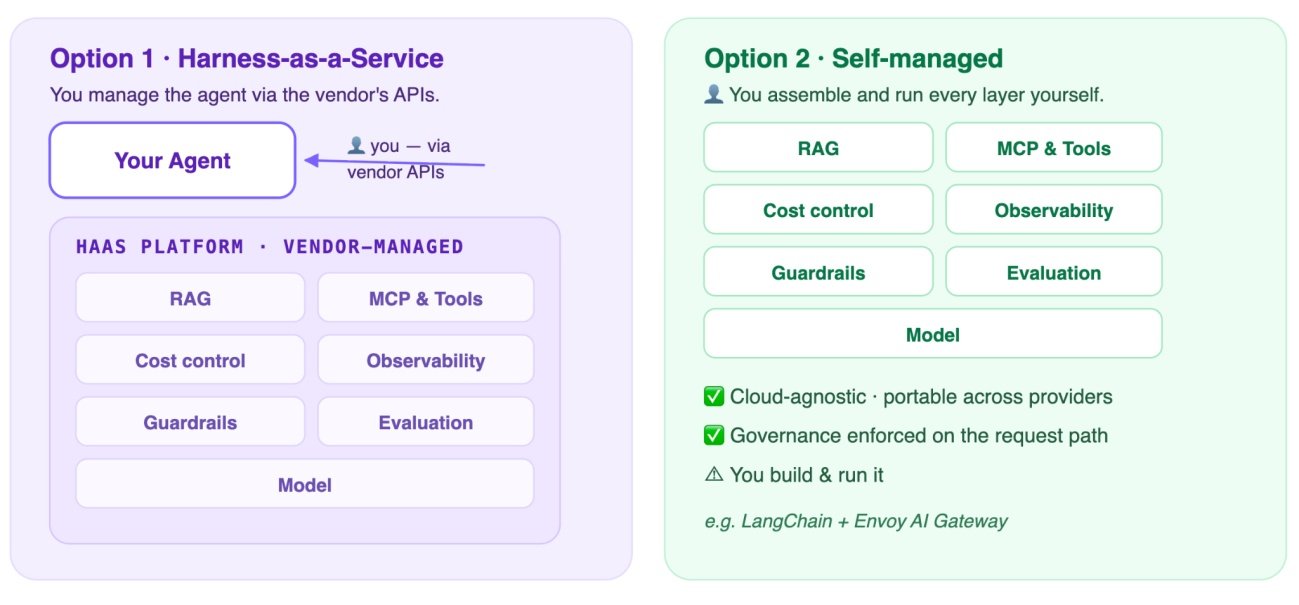
When engineering teams set out to construct a production-ready agent, they generally choose between two distinct architectural methodologies: Harness-as-a-Service (HaaS) and self-managed infrastructure.
Harness-as-a-Service solutions—such as Amazon Bedrock AgentCore, Google Vertex AI Agent Engine, Azure AI Foundry Agent Service, and the LangGraph Platform—provide a vendor-run runtime environment. These managed services expose the entire harness development and operations lifecycle through managed application programming interfaces. Organizations configure parameters such as identity management, memory retention strategies, and execution limits, while the cloud provider handles underlying container lifecycles, microVM isolation, and automatic tracing.
Alternatively, self-managed architectures give engineering teams granular control by assembling open-source components and software development kits on cluster orchestration platforms like Kubernetes. Organizations leveraging this approach often combine frameworks like LangChain or LlamaIndex with dedicated routing layers such as Agent Router (formerly Envoy AI Gateway) or LiteLLM. This model allows enterprises to maintain cloud-agnostic deployments, ensuring that switching between underlying foundation model providers requires only configuration updates rather than deep application rewrites.
The strategic choice between HaaS and self-managed stacks typically depends on organizational priorities. Companies aiming to accelerate time-to-market without assuming infrastructure maintenance burdens lean toward managed services. Conversely, organizations with strict data residency requirements, multi-cloud mandates, or the need for hyper-specific security integrations frequently invest in self-managed routing and telemetry stacks.
Comparative Analysis of Production Agent Frameworks
| Architectural Dimension | Harness-as-a-Service (HaaS) | Self-Managed Infrastructure |
|---|---|---|
| Core Architecture | Vendor-managed runtime exposing dev and ops capabilities via managed APIs. | Custom assembly of SDKs, open-source gateways, and orchestration tools. |
| Enterprise Ownership | Policies, token budgets, system prompts, tool definitions, and evaluations. | Application code plus deployment, cluster upgrades, and on-call rotations. |
| Ecosystem Binding | Tied closely to the specific cloud provider’s runtime ecosystem and API contracts. | Bound to chosen open-source software stacks and container orchestration tools. |
| Representative Platforms | AWS AgentCore, Google Vertex AI, Azure AI Foundry, LangGraph Platform. | LangChain, LlamaIndex, Envoy AI Gateway, LiteLLM on Kubernetes. |
| Optimal Use Case | Rapid product delivery without dedicated platform engineering overhead. | Cloud-agnostic deployments requiring strict data control and custom routing. |
Practical Implementation: Analyzing FinBot Architecture
To evaluate the operational differences between these two methodologies, engineers often examine reference implementations such as FinBot, a canonical financial assistant designed to ingest corporate filings, execute code-based numerical analysis, and synthesize executive summaries.
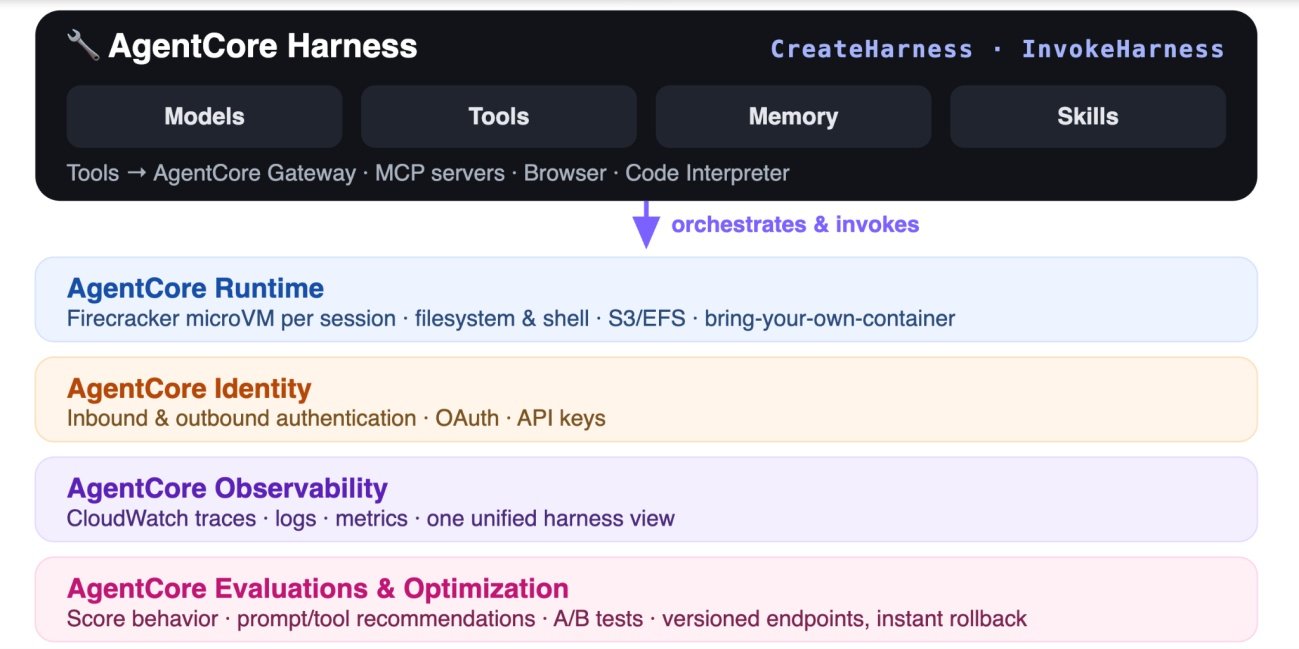
In a managed HaaS environment like AWS AgentCore, constructing FinBot involves declaring system parameters, tool integrations, and memory retention policies within a centralized control-plane configuration. The managed runtime automatically provisions isolated execution sandboxes—such as Firecracker microVMs—per user session, manages semantic memory layers, and handles telemetry propagation without requiring manual instrumentation of the underlying application code.
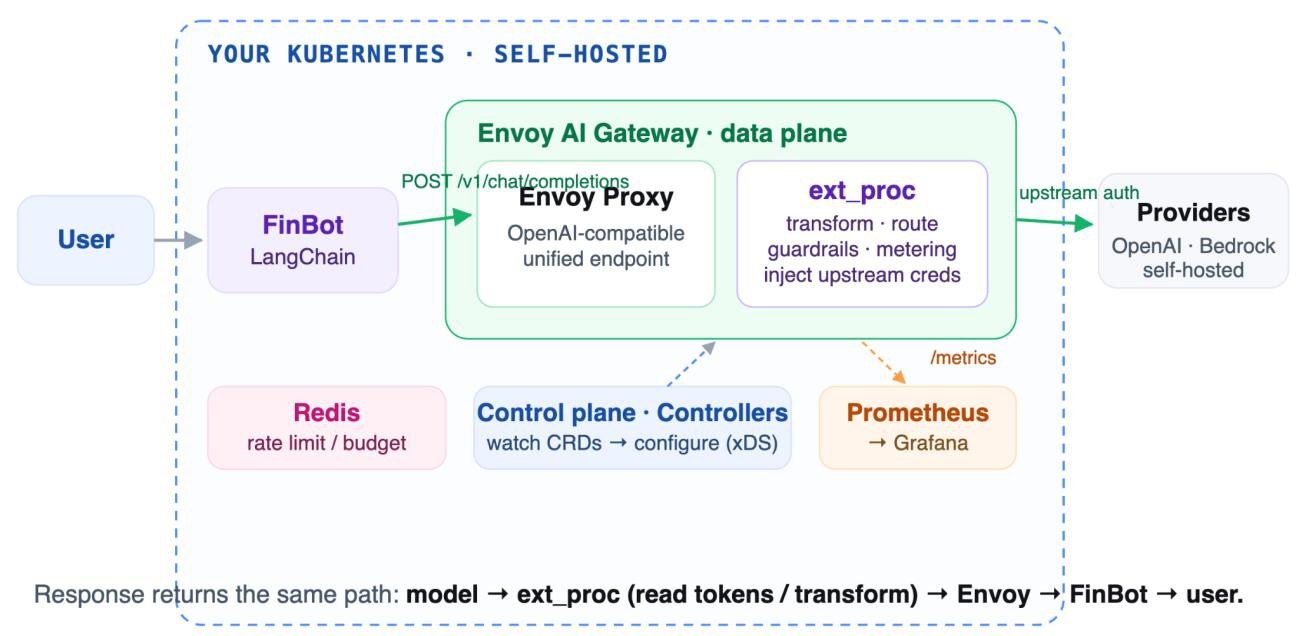
In a self-managed equivalent deployed on Amazon Elastic Kubernetes Service (EKS), the architecture decouples model access from application logic. An AI gateway acts as the single entry point for all generation traffic, enforcing token-based rate limits, managing provider failovers, and injecting authentication credentials securely through workload identity integrations. OpenTelemetry collectors scrape standardized metrics across the cluster, aligning spans from both the agent application code and the gateway routing layer to construct a unified trace of the prompt-tool-response execution chain.
Operational Implications and Enterprise Outlook
As artificial intelligence agents transition from experimental novelties to core enterprise software components, the importance of the agent harness will only intensify. Industry analysts project that enterprise spending on governance, observability, and infrastructure scaffolding will outpace raw model acquisition costs as organizations prioritize predictability, regulatory compliance, and cost containment.
By establishing clear operational boundaries, implementing rigorous cost guardrails, and enforcing unified observability across multi-provider environments, engineering teams can successfully mitigate the inherent non-determinism of large language models. Whether organizations adopt fully managed platform services or deploy sophisticated open-source gateways on Kubernetes, the mastery of the agent harness remains the definitive factor separating fragile prototypes from resilient, production-ready enterprise applications.