Failure Mode and Effects Analysis: A Strategic Framework for Mitigating High-Stakes Operational Risk

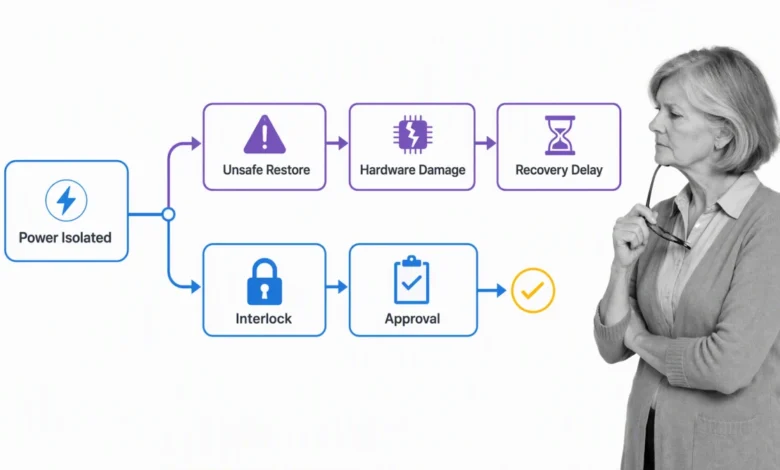
In the complex ecosystem of modern enterprise, the difference between a minor operational hiccup and a catastrophic service failure often comes down to the rigor of proactive risk assessment. Organizations across aerospace, healthcare, and critical infrastructure rely on a methodology known as Failure Mode and Effects Analysis (FMEA) to dissect potential vulnerabilities before they manifest into reality. By systematically identifying how processes, products, or services might fail, teams can quantify risks and implement robust preventive controls, effectively turning the "worst-case scenario" mindset into a disciplined competitive advantage.
The 2017 British Airways IT collapse serves as a seminal case study in why this methodology is essential. What began as a localized power issue snowballed into a global operational paralysis, resulting in an estimated gross cost of approximately £80 million and the disruption of travel plans for roughly 75,000 passengers. The incident underscored a fundamental truth of interconnected systems: a failure at a single, seemingly isolated node can propagate through an entire operation with devastating velocity.
Understanding the Mechanics of FMEA
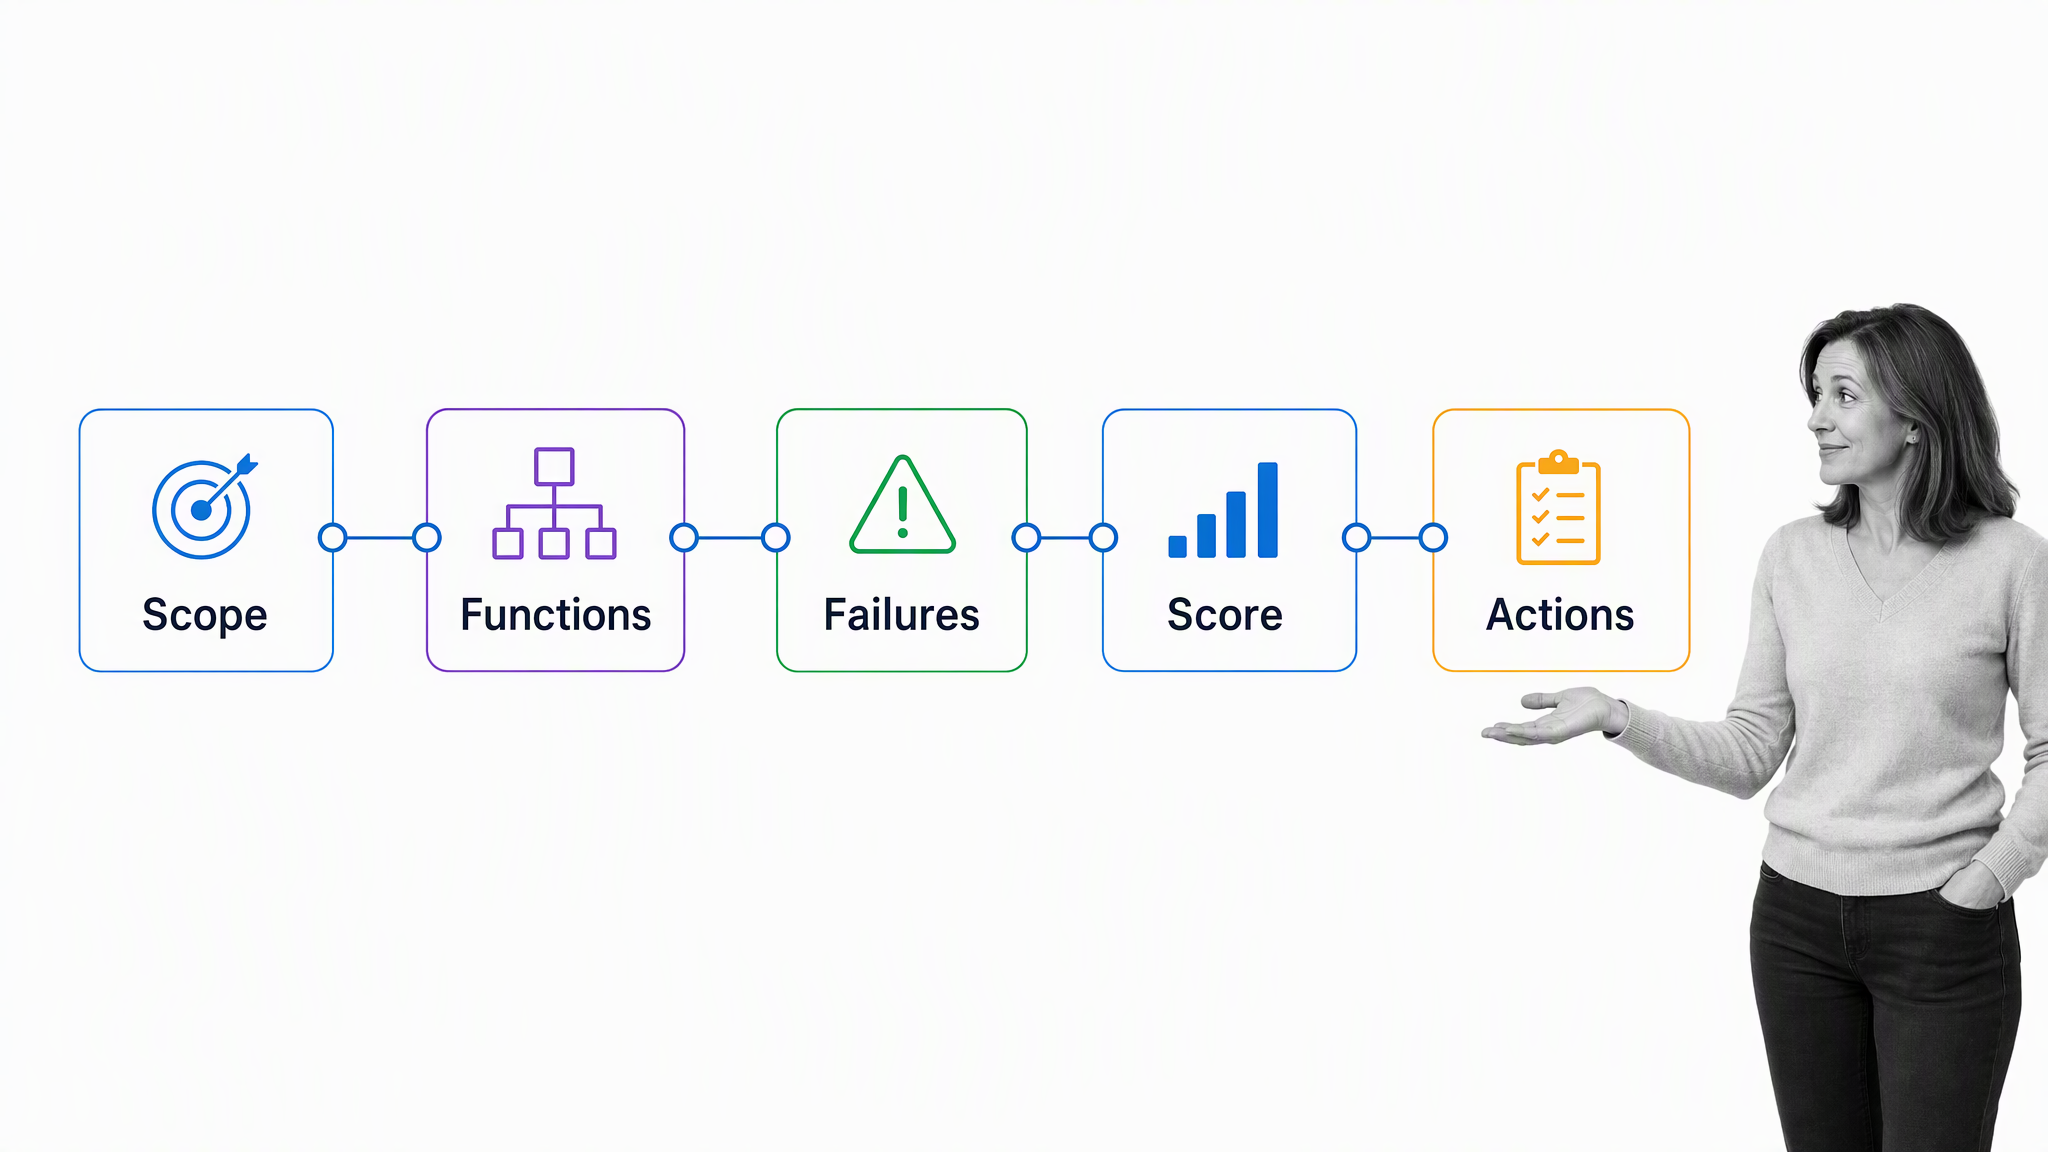
At its core, FMEA is a structured, analytical technique designed to identify the various "failure modes"—the ways in which a specific component, task, or system can deviate from its intended function. Each failure mode is subjected to an "effects analysis," which maps the causal chain of that failure to its ultimate impact on the end user, business operations, and organizational reputation.
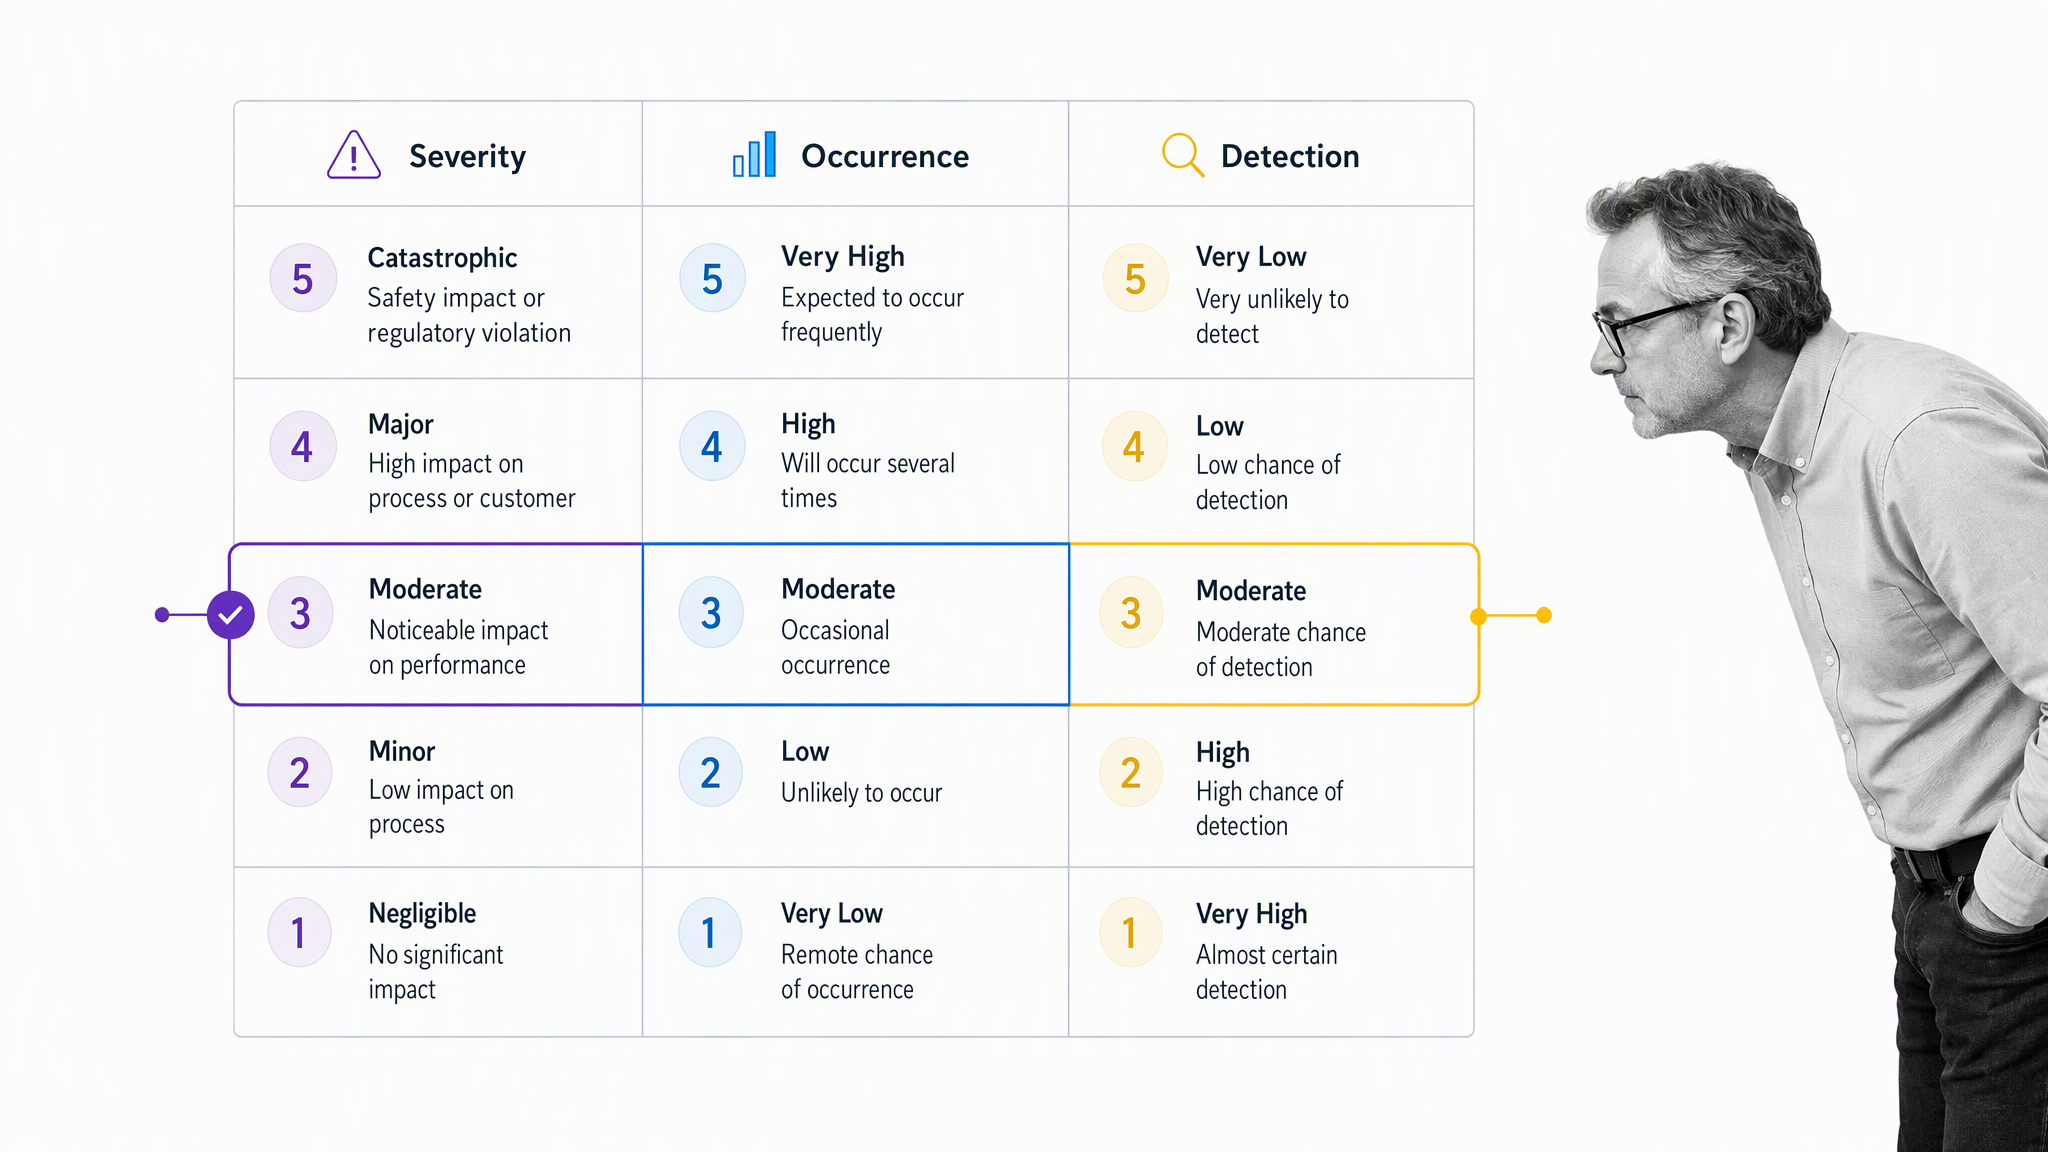
The evaluation typically relies on a three-pronged scoring system:
- Severity (S): Assessing the impact of the failure on the customer or the business.
- Occurrence (O): Evaluating the likelihood or frequency of the failure event.
- Detection (D): Measuring the capability of current controls to identify the failure before it results in a negative outcome.
By calculating a Risk Priority Number (RPN) or utilizing a criticality matrix (S × O), leadership teams can establish a hierarchy of risk. This ensures that resources are not squandered on low-impact issues, but rather concentrated on the most dangerous, frequent, or elusive failure points.
The British Airways Incident: A Chronology of Cascade
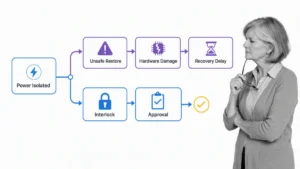
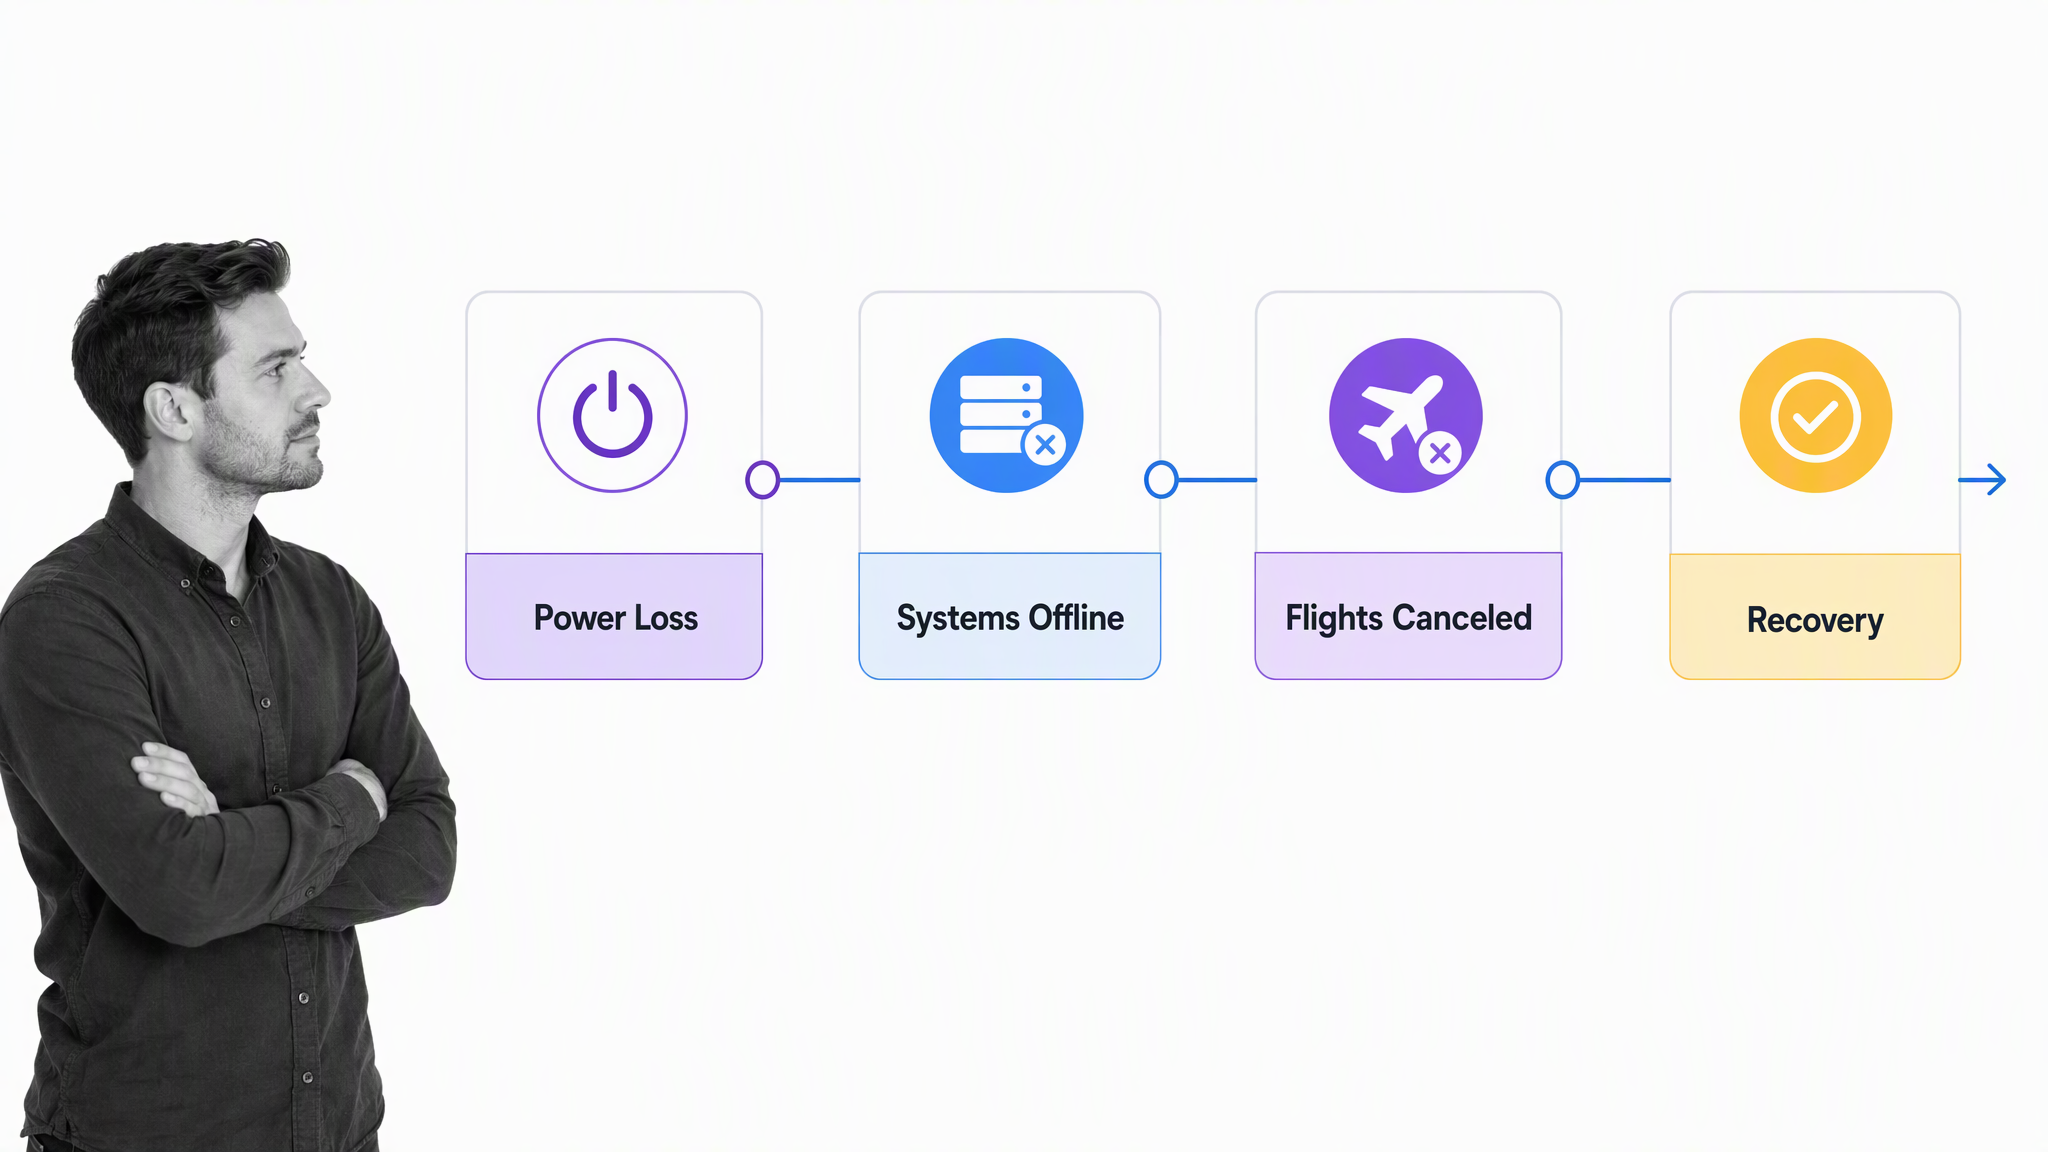
On the morning of May 27, 2017, a critical power interruption occurred at a data center facility utilized by British Airways in the United Kingdom. While the precise sequence of events remains a subject of detailed technical scrutiny, the narrative of the failure is clear: the interruption was compounded by an uncontrolled surge during the power restoration process. This surge caused physical damage to sensitive IT hardware, effectively crippling the airline’s core operating systems.
The timeline of the disruption was as follows:
- Saturday, May 27: Power loss occurs at the data center, immediately triggering system-wide failures. Check-in, baggage handling, and flight dispatch systems go offline.
- Sunday, May 28: The scale of the IT collapse becomes clear. British Airways cancels all flights from Heathrow and Gatwick for the remainder of the day.
- Monday, May 29: Operations begin a tentative recovery, though long-term backlogs and aircraft displacement continue to cause significant delays.
- Post-Incident: Investigations reveal that the failure was not merely a power issue, but a failure of redundant systems and recovery protocols.
The financial and operational fallout was immediate. Beyond the £80 million in direct gross costs, the airline faced significant compensation claims under EU regulations, increased expenditure for third-party hotel and rebooking services, and, most critically, a tangible blow to consumer trust.
Analytical Implications: Why Systems Fail
The British Airways case highlights a common pitfall in risk management: the over-reliance on human intervention rather than engineered, automated controls. The incident raised critical questions regarding procedural governance:
- Authorization and Oversight: Was the restoration procedure clearly documented, and were there non-negotiable "stop-points" for manual intervention?
- Technical Interlocks: Were there hardware-level safeguards in place to prevent an unsafe power restart?
- Redundancy Validation: Were the failover plans actually tested under stress conditions, or did they exist only as theoretical documents?
Treating the incident as mere "human error" is a reductive approach that ignores the systemic failures of the environment in which those humans were operating. A robust FMEA process would have likely identified the "uncontrolled restoration" path as a high-risk failure mode, triggering the implementation of automated interlocks or mandatory multi-person verification steps.
When to Deploy FMEA
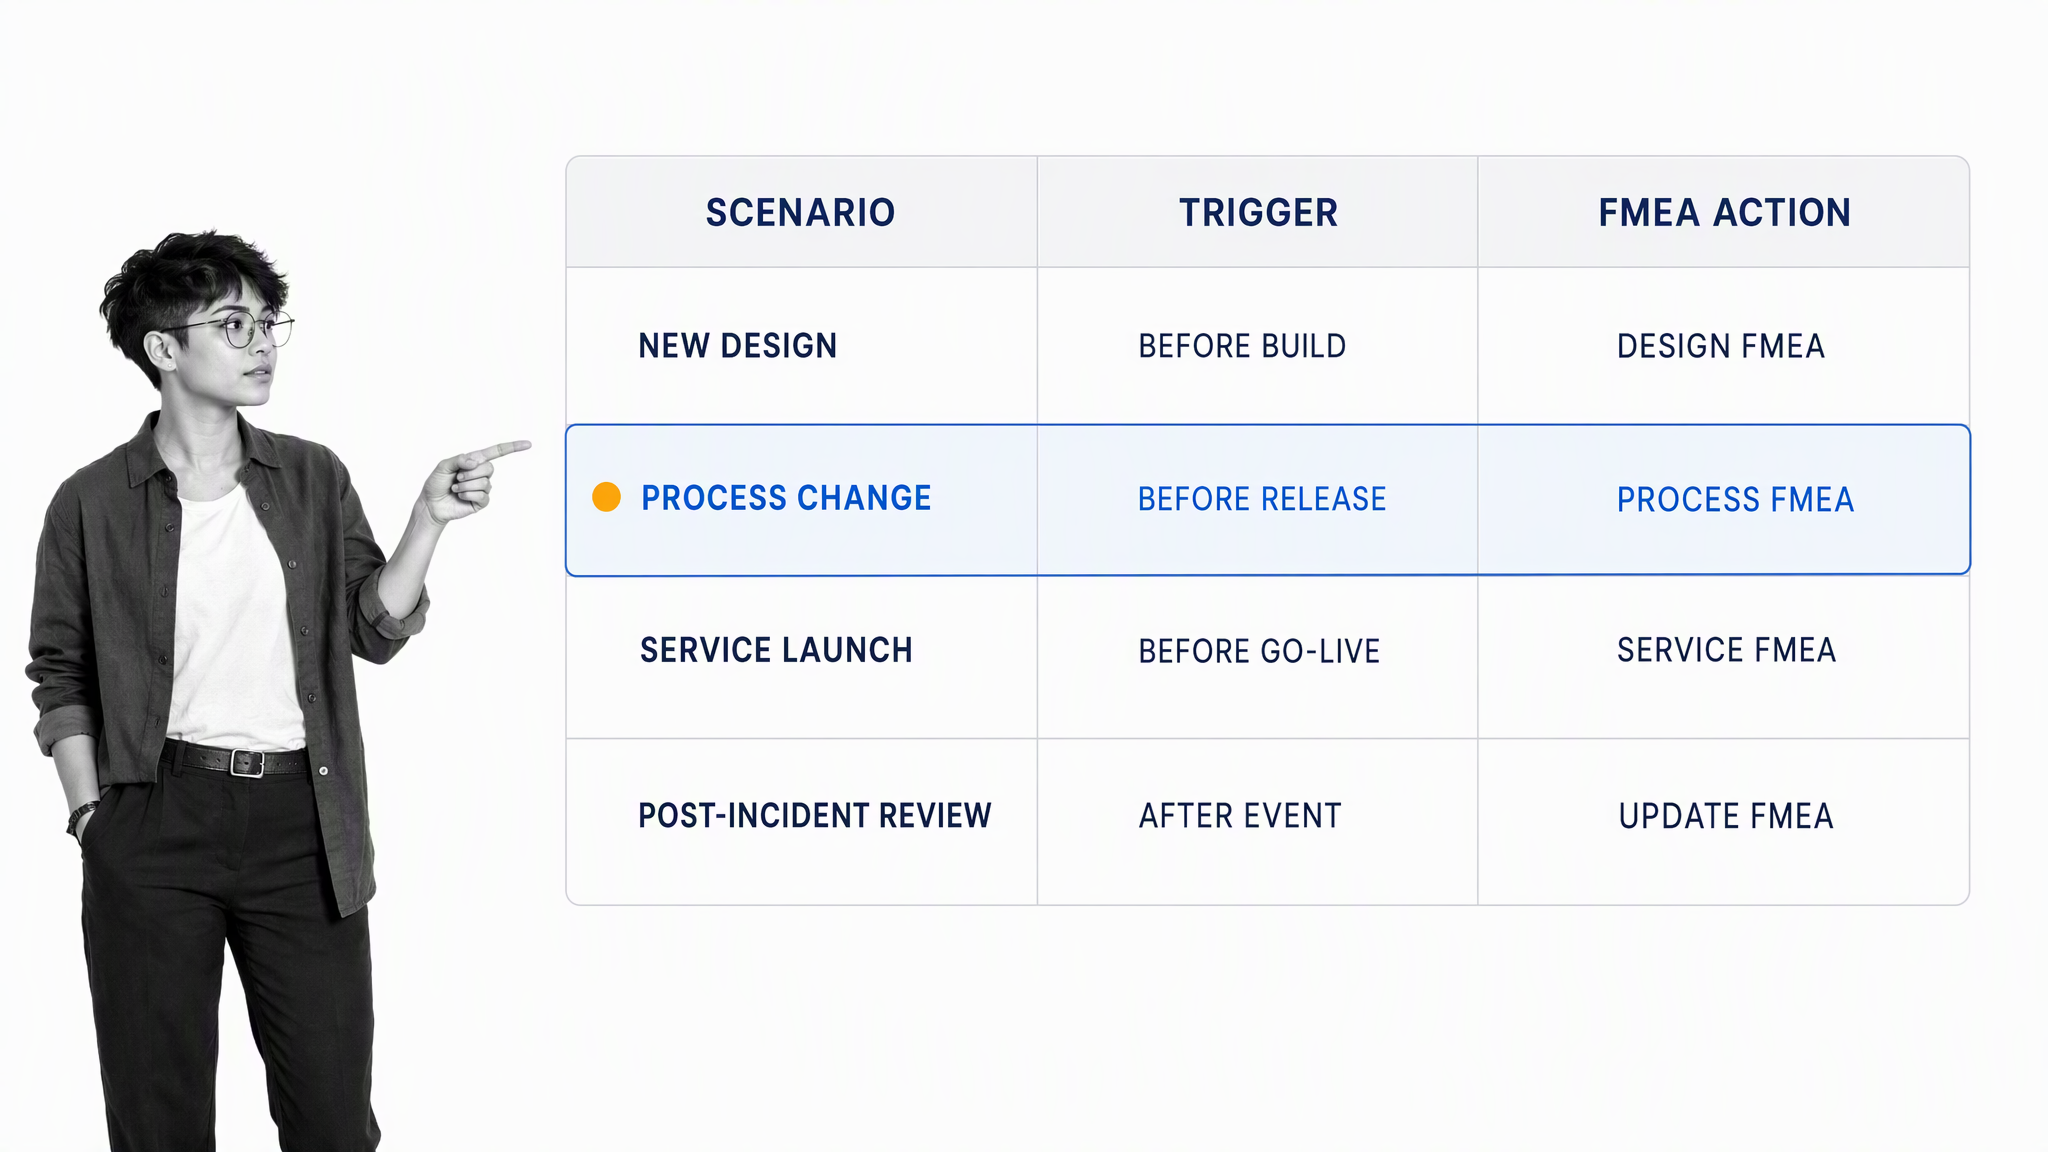
While continuous process improvement is a standard goal for high-performing organizations, FMEA is most effective at specific "inflection points" in an organization’s lifecycle.
1. During New Process Design
When designing a new service or internal policy, FMEA acts as a "stress test." By mapping the workflow, teams can simulate potential failure points—such as staff turnover, software integration errors, or resource bottlenecks—before the process is ever deployed.
2. During Significant Process Re-engineering
Whenever a change is introduced—such as migrating to a new data center, implementing a new CRM, or shifting to a remote-first policy—the existing risk landscape changes. FMEA allows teams to detect the "new" problems that emerge from these adaptations.
3. Following Systemic Failure
Perhaps the most crucial, yet often neglected, use case is the post-mortem. After a disaster, the focus must shift from blame to structural prevention. By applying FMEA to the incident, an organization can codify the lessons learned into the DNA of the process, ensuring that the "normalization of deviance"—the gradual acceptance of risky practices—is actively countered.
Best Practices for Implementation
To be effective, FMEA must be a collaborative, cross-functional exercise. It should not be relegated to a siloed department or a single spreadsheet. An effective FMEA session requires:
- Diverse Stakeholders: Including engineers, frontline operators, IT staff, and customer success representatives ensures that the analysis is grounded in reality rather than theoretical assumptions.
- Evidence-Based Scoring: Subjective guesses regarding severity and frequency should be replaced with historical data and empirical testing whenever possible.
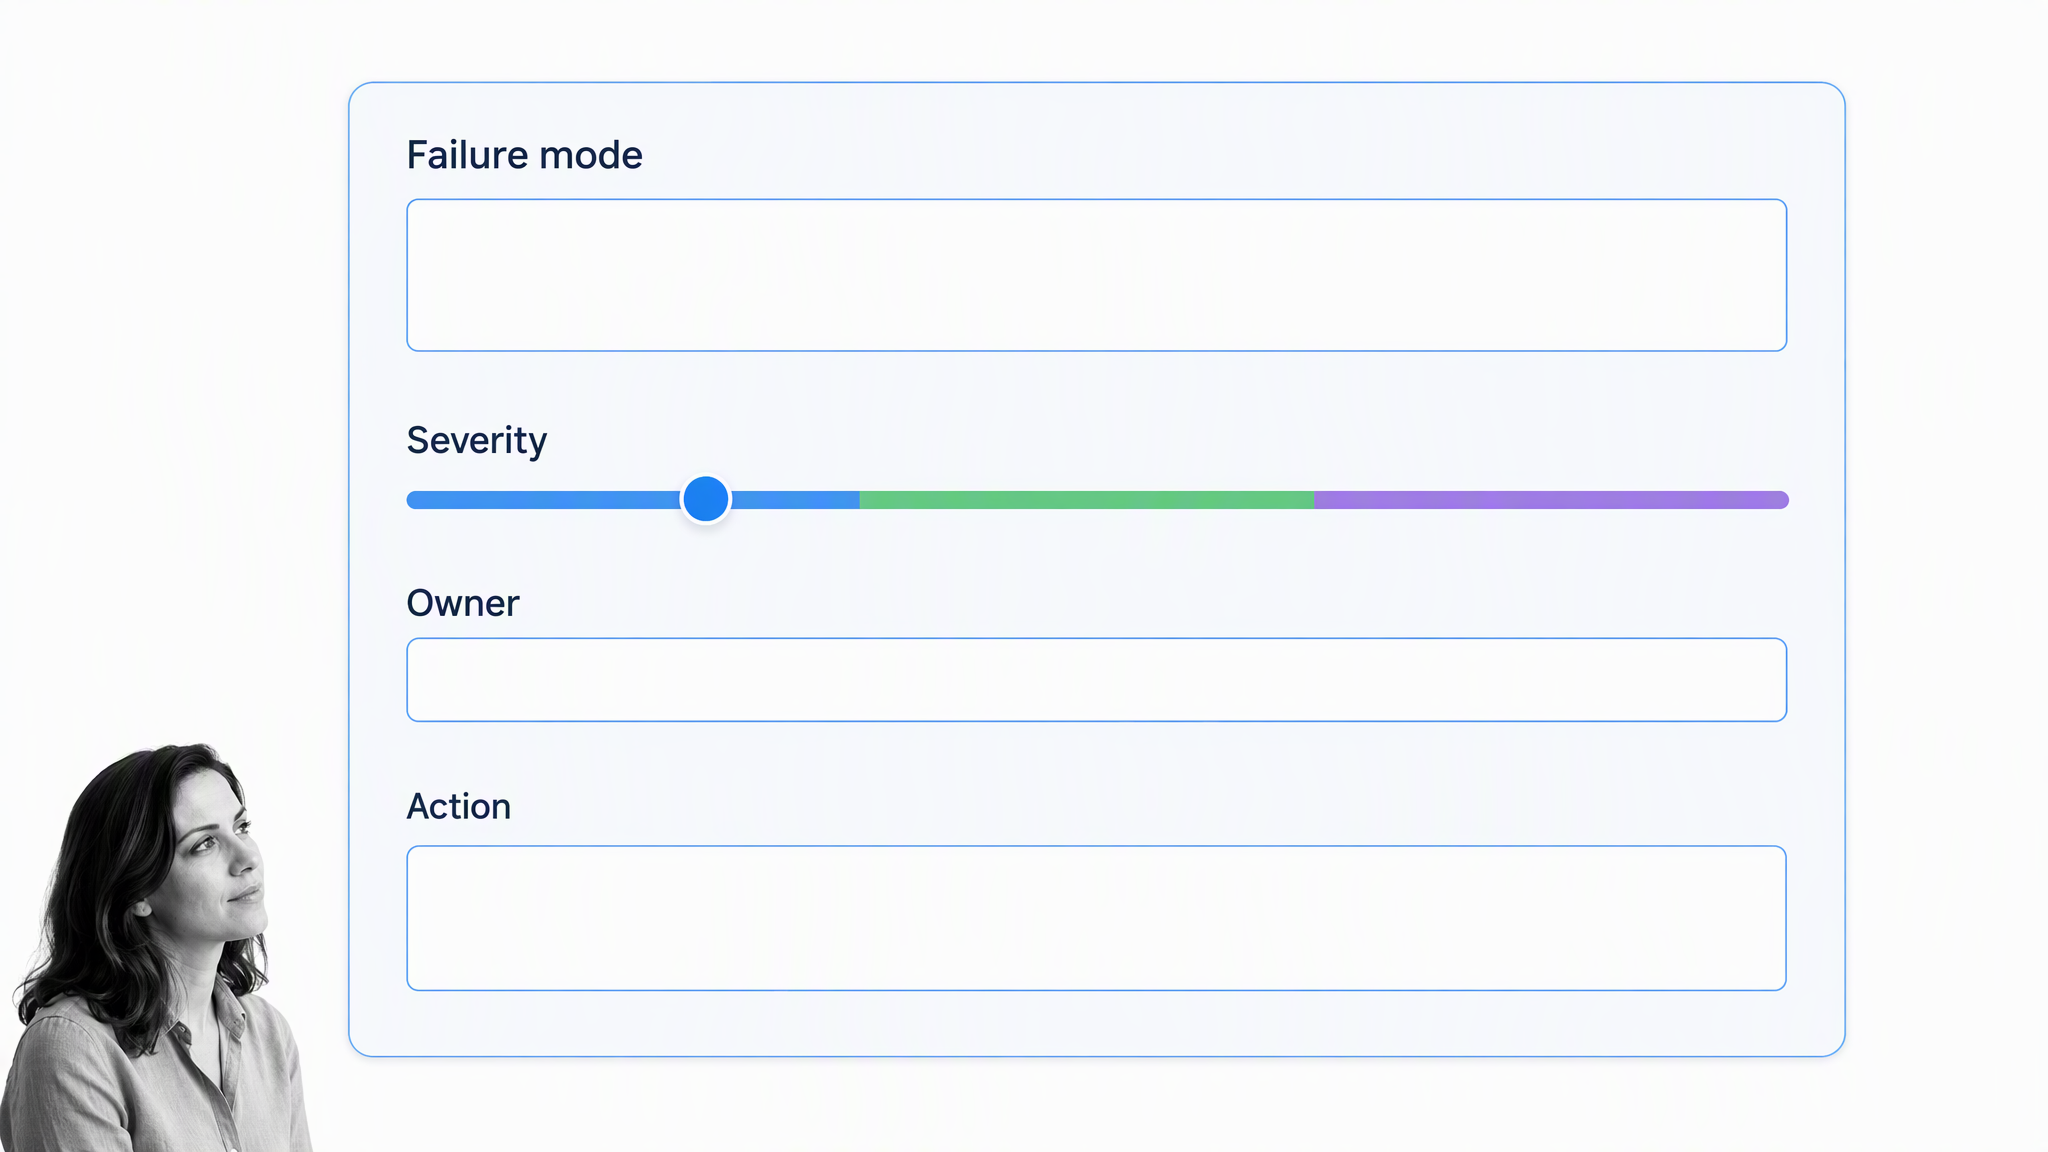
- Accountability: Every identified high-risk failure mode must be assigned to an owner, with a clear deadline for the implementation of a preventive or detective control.
- Audit Trails: Documentation is vital. Organizations must maintain a record of the FMEA, including the logic behind the scoring and the status of corrective actions. This is essential for compliance audits and for re-evaluating the analysis when conditions change.
Conclusion: From Pessimism to Proactive Resilience
The discipline of Failure Mode and Effects Analysis is, in many ways, an exercise in professional skepticism. It requires a team to look at a functioning, efficient system and ask, "How could this fall apart?" While the exercise can seem inherently pessimistic, its outcome is profoundly constructive.
By proactively identifying the weaknesses in a system—whether it is a data center power grid or a customer service workflow—organizations can design controls that limit the impact of inevitable failures. As shown by the British Airways incident, the cost of failing to perform this due diligence is measured in millions of pounds, lost time, and damaged reputation. In an increasingly interconnected global market, the ability to anticipate and neutralize failure before it occurs is no longer an optional best practice; it is a fundamental requirement for business survival.
Effective risk management, supported by tools that integrate documentation with operational execution, allows organizations to move beyond reactive fire-fighting. Instead, they can build resilient, self-correcting systems that maintain their integrity even when individual components falter. In the final analysis, FMEA provides the map for navigating the uncertainties of complex operations, ensuring that when the unexpected happens, the impact is contained, the path to recovery is clear, and the lessons learned are never forgotten.