How to Turn an Open-Weight Language Model Into a Decision Model for Automated Intent Classification

In the rapidly evolving landscape of artificial intelligence, the focus is shifting from generative text models that provide long-form prose to precision-oriented decision models capable of executing structured tasks. While traditional Large Language Models (LLMs) like GPT-4 or Claude are optimized for conversational creativity, many industrial applications—ranging from banking support to automated routing—require discrete, reliable outputs. A new methodology, facilitated by the Unsloth library, now allows developers to transform open-weight models such as Qwen3.5-4B into highly efficient decision-making engines. By fine-tuning these models on structured datasets like CLINC150, organizations can bypass the latency and unpredictability of generative text in favor of rapid, deterministic classification.
The Shift from Generation to Classification
The fundamental difference between a generative model and a decision model lies in the output mechanism. Standard LLMs function as probabilistic engines that predict the next token in a sequence, often resulting in verbose, unpredictable, and sometimes "hallucinated" responses. Conversely, a decision model is engineered to operate on a closed-loop system: it receives an input, evaluates it against a predefined set of choices, and returns a structured probability score for each.
Models such as Jev, Laya, and Clef have popularized this approach, demonstrating that for tasks like intent detection or sentiment analysis, a model does not need to explain its reasoning; it simply needs to be correct. By integrating a specialized "decision head" onto a base language model, engineers can constrain the output space, ensuring that the model returns machine-readable JSON formats rather than unstructured natural language. This architecture is increasingly vital for enterprise workflows where reliability, low latency, and auditability are paramount.
Methodology and Technical Implementation
The recent integration of decision-model training into the Unsloth framework marks a significant reduction in the barrier to entry for developers. Utilizing Qwen3.5-4B as the foundation, the process leverages 4-bit LoRA (Low-Rank Adaptation) to fine-tune the model with minimal hardware requirements. This approach is particularly effective in environments like Google Colab, where memory constraints often prevent the training of full-parameter models.
The training process follows a specific chronology:
- Environment Setup: The deployment of the Unsloth library, which optimizes GPU utilization through custom kernels, ensuring that training is significantly faster than standard Hugging Face implementations.
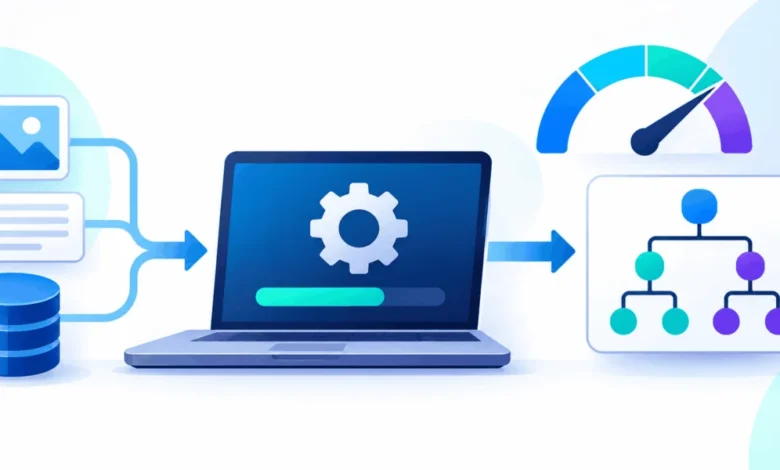
- Data Transformation: Converting natural language datasets into the "Choice" format. This involves pairing user queries with a set of instructions, a list of potential criteria, and a "gold" label representing the ground truth.
- LoRA Integration: Applying adapter layers to the base model. By training only a small fraction of the model’s parameters—approximately 2% in the case of the CLINC150 experiment—the system retains the linguistic intelligence of the base model while mastering the classification task.
- Calibration: Utilizing specialized calibration techniques to ensure that the model’s confidence scores accurately reflect its performance, a critical requirement for production-grade reliability.
Analyzing the CLINC150 Benchmark
To validate this approach, researchers often utilize the CLINC150 dataset, a gold-standard collection in the field of intent detection. The dataset contains 150 distinct intent categories across diverse domains, including finance, travel, and personal assistant tasks. In a recent pilot study, 10 specific intents were isolated to test the efficacy of the Qwen3.5-4B fine-tuning.
The results were notable: baseline performance, prior to fine-tuning, hovered around 18.5% accuracy—consistent with random guessing across ten categories. After a brief training cycle of 60 steps, the model reached a 100% accuracy rate on the validation and test sets. While this perfect score is specific to a controlled, ten-category experiment, it highlights the potential for high-precision performance when models are trained on domain-specific datasets rather than general-purpose corpora.
Data Calibration and Confidence Scores
One of the primary challenges in deploying AI models in high-stakes environments is the "overconfidence" problem, where a model provides a wrong answer with high certainty. The Unsloth implementation addresses this through the use of Expected Calibration Error (ECE). ECE serves as a metric to measure the gap between predicted confidence and actual accuracy.
In the experimental setup, post-training calibration reduced the ECE to approximately 0.0019, suggesting that when the model reports a 99% probability for a specific intent, it is correct 99% of the time. This statistical reliability is the cornerstone of trust in automated systems, allowing developers to set thresholds for "Human-in-the-loop" handoffs. For instance, if a decision model reports an intent confidence score below 0.85, the system can be configured to automatically escalate the request to a human agent, thereby mitigating the risk of incorrect automation.
Broader Implications for Enterprise AI
The ability to train custom decision models using open-weight architectures carries significant implications for data privacy and operational autonomy. Many companies are hesitant to send sensitive user queries to third-party APIs due to compliance concerns (e.g., GDPR, HIPAA). By fine-tuning a small, efficient model like Qwen3.5-4B, businesses can host the entire classification pipeline on-premises or within a private cloud environment.
Furthermore, the shift toward decision models aligns with the industry’s focus on cost-efficiency. Generative models incur high costs due to their computational requirements for generating long token sequences. A decision model, by contrast, stops at the classification layer, significantly reducing the compute time per request. This optimization allows for higher throughput in high-volume environments, such as customer service chatbots or real-time network routing.
Future Trajectories
As developers continue to refine these workflows, the next frontier for decision models lies in "out-of-scope" (OOS) detection. While the current experiment focused on classifying known intents, real-world deployment requires a robust ability to identify when a user request falls outside the model’s capabilities. Future iterations of decision-model training will likely incorporate automated OOS handling, where the model is explicitly trained to reject inputs that do not align with any defined category.
Moreover, the scalability of this method—using larger models or expanding the number of intents—remains an area of active investigation. While 4-bit LoRA is effective, researchers are exploring how parameter-efficient fine-tuning can be combined with distillation to produce even smaller, faster models that maintain high accuracy.
In conclusion, the transformation of general-purpose language models into specialized decision engines represents a maturation of AI deployment strategies. By focusing on intent, accuracy, and calibrated confidence, developers can move beyond the "chat" paradigm and build functional, high-reliability systems that serve as the backbone for modern digital infrastructure. The tools provided by platforms like Unsloth are not merely optimizations; they are foundational components that allow for the democratization of high-performance AI, placing the power of precision-tuned intelligence into the hands of a broader development community.